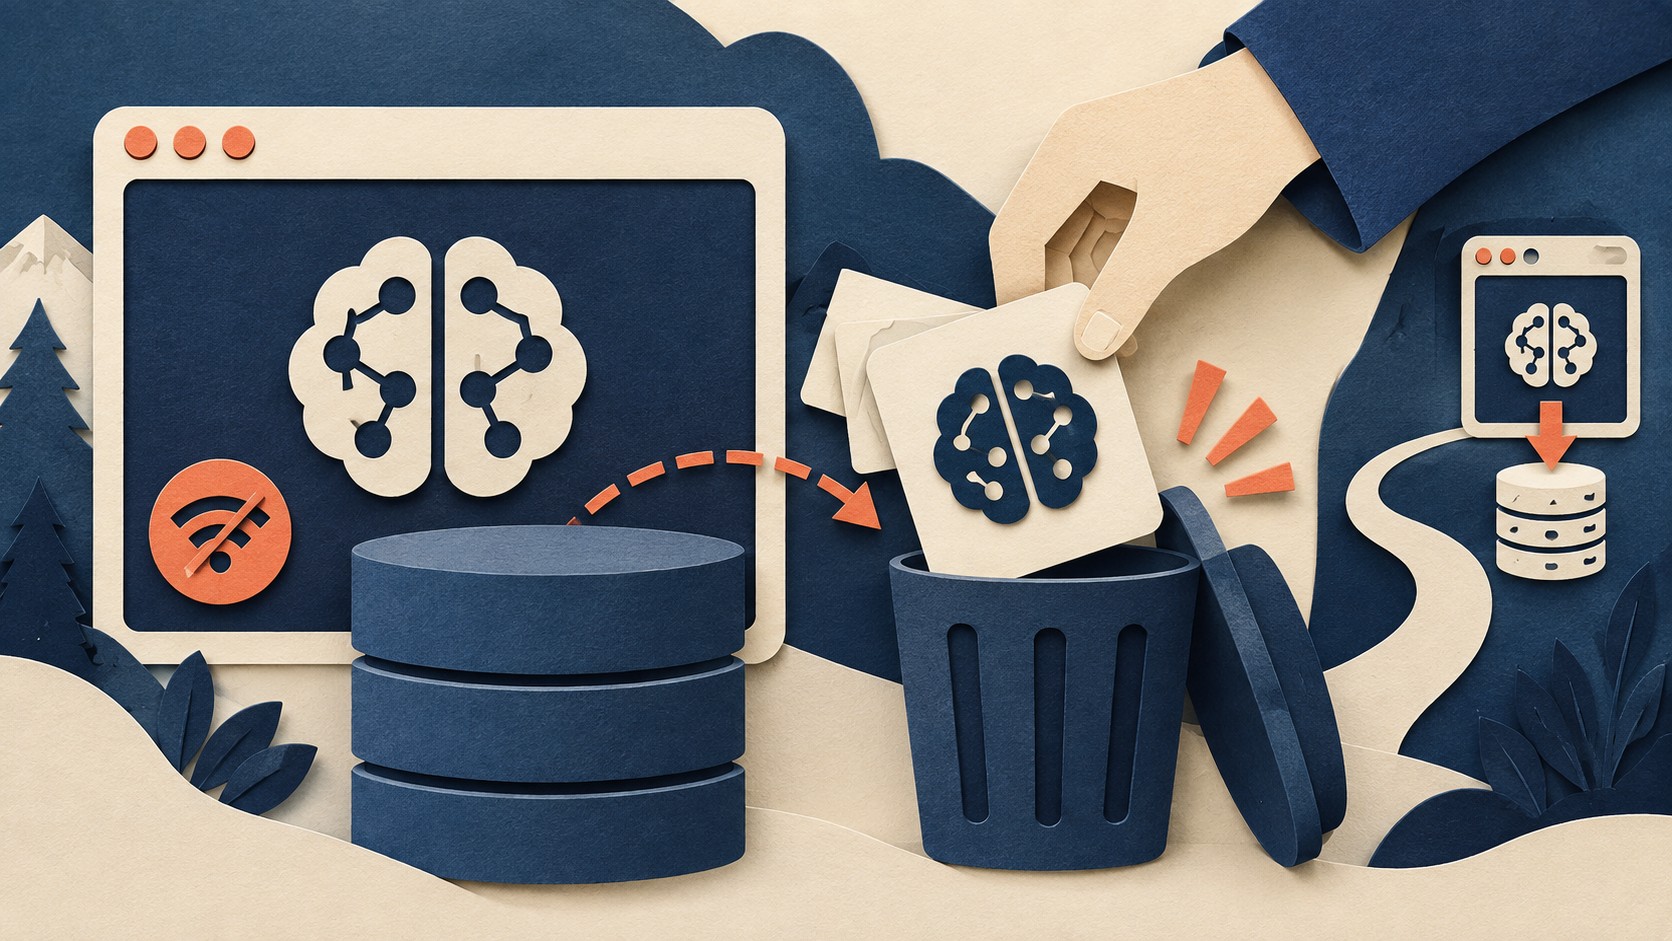
An offline AI app may work today and ask for its model again later. The model was downloaded, but the browser can remove data that a site stores locally. Browser storage is usually best effort: it remains available while the site stays within its quota, the device has space, and the user leaves the data in place. Storage pressure can also trigger automatic eviction. An app that promises offline use needs a plan for the moment its model is gone. MDN explains the storage rules.
The model shares the site’s storage
Browsers commonly manage storage by origin: the web address’s scheme, hostname, and port. Pages on the same origin share its storage limits. An app might keep model files in the Origin Private File System, IndexedDB, or the Cache API. It might use a service worker and the Cache API for the pages and scripts needed to open offline. These stores have different jobs, but they are all subject to browser storage management. MDN describes the storage options and how cached resources support offline pages.
That shared limit matters. A successful model download does not reserve permanent space for the model. Other data from the same origin also counts toward its storage use. Keeping the interface available offline and keeping the model available offline are related tasks, but the app must check both.
A quota estimate cannot promise space
Browsers set different limits, and the available space on the device may prevent an app from reaching its stated quota. navigator.storage.estimate() reports approximate usage and quota for an origin. Its values are imprecise, so they can guide a download decision without guaranteeing that the next write will succeed. MDN documents the estimate and the limits behind it.
When a write exceeds the origin’s quota, storage APIs such as IndexedDB, Cache, and the Origin Private File System can fail with QuotaExceededError. That failure calls for a useful message and a way to free space or choose a smaller download. It does not mean the browser has evicted the entire site. The app should confirm that every required model file was saved before marking a download ready. MDN distinguishes quota failures from eviction.
Eviction removes the origin’s data
Under storage pressure, browsers can evict a best-effort origin that has not been used recently. MDN says browser eviction removes the origin’s stored data together, including data in IndexedDB and the Cache API. Safari can also remove script-created data for origins without recent user interaction under its tracking-prevention policy. Private browsing commonly uses different limits and usually removes stored data when the private session ends. These cases are covered in MDN’s eviction guide.
For an offline AI app, losing the model is only part of the problem. The cached page and scripts may disappear too. If those files are needed to launch the app, it may need a network connection before it can even show a recovery screen. A service worker can serve cached resources while they exist; it cannot serve a resource that is no longer there. That follows from MDN’s account of origin-wide eviction and its offline caching guide.
Persistent storage narrows the risk
An app can call navigator.storage.persist() to request persistent storage. The request can be denied, and browser rules for granting it differ. The app can check its status with navigator.storage.persisted(). When persistence is granted, the browser protects the origin from its automatic storage-pressure eviction. The user can still clear the site’s data, and writes can still hit a quota. MDN explains the request and Google’s persistent-storage guide explains the status check and when to ask.
The request makes the most sense when the user is saving something important. It should not become a promise that a model or a private conversation will remain on the device forever. The app still needs to inspect what is present when it starts.
Recovery needs a visible path
A model picker should distinguish ready, downloading, missing, and download failed. On launch, the app should check for the files it needs before offering offline generation. If a model is missing, it should say so plainly. When online, it can offer a fresh download with progress and a clear completion state. When offline, it should explain that generation will be available after the model is restored.
The same-origin rule also shapes the treatment of user-created data. A browser eviction can remove local conversations or settings stored beside the model. An app should give users a way to export anything they cannot easily recreate, or offer an explicit sync choice where that fits its privacy promise. Redownloading a model cannot recover a conversation that existed only in evicted browser storage. This recommendation follows from MDN’s description of origin-wide eviction.
What to do
- Show storage use before a large download. Use
navigator.storage.estimate()as a guide, label it an estimate, and handle a write failure even when the estimate looked sufficient. MDN documents both behaviors. - Ask for persistence when the user saves critical local data. Check whether the browser granted it. Keep the recovery flow either way. Google’s guide recommends asking in the context of a user action.
- Verify the model at startup. Show a ready state only after the required files are present and usable. Give a failed or interrupted download its own state.
- Make loss understandable. Explain when the model must be downloaded again, and provide a route back to use when connectivity returns. Keep an offline fallback for resources that remain cached. MDN shows how a service worker can provide one.
- Protect irreplaceable work. Offer export or an explicit sync option for local conversations and settings. Tell users that clearing site data can remove them. MDN identifies user deletion as a limit of browser storage.
The Campfire
No commentsNobody has pulled up a log by this one yet. Be the first to say what you make of it.
Held for the desk. It appears after a look.