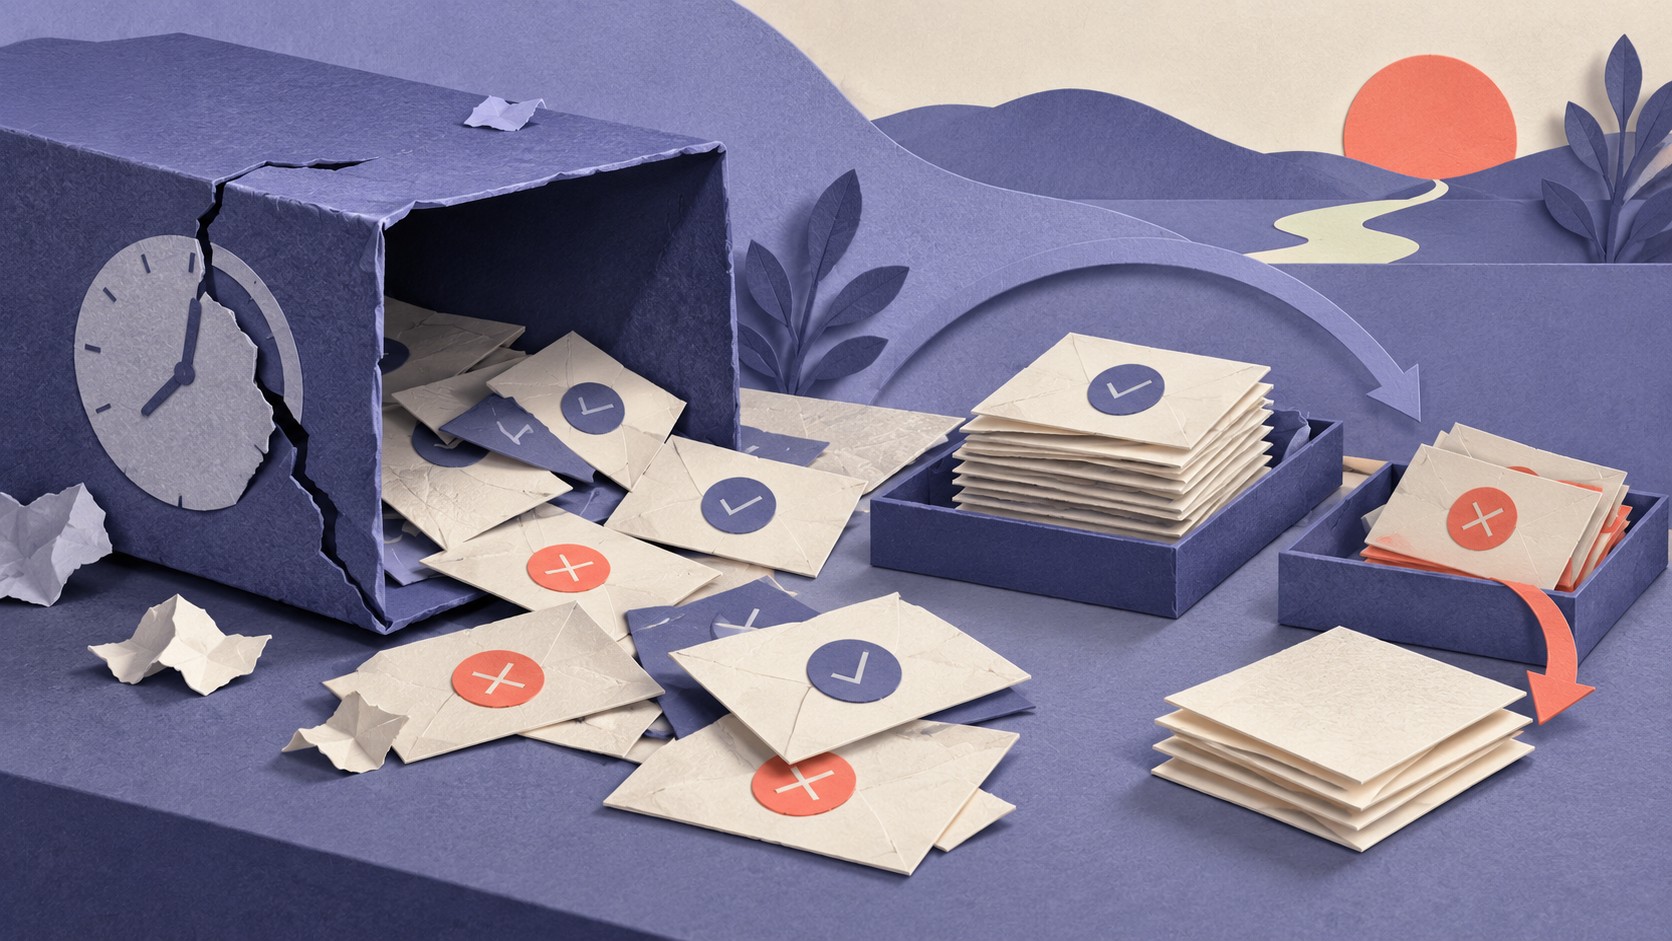
A batch can expire after useful work has already finished. OpenAI says unfinished requests are cancelled at expiry, while responses from completed requests remain available in the output file. Completed requests still consume billable tokens. That makes expiry a reconciliation problem: decide which input lines produced usable results, which expired, and which failed for another reason. The Batch API guide describes the files and identifiers needed to make that decision.
Give every request a durable identity
A batch starts as a JSON Lines input file. Each line holds one request and a unique custom_id. OpenAI returns that ID with each output line, so it can connect a result to the original request. The guide also warns that output lines can arrive in a different order from input lines. Position is therefore a poor key for matching work to results. OpenAI documents the input and output formats.
Choose an ID that points to a stable record in your own system. Keep a manifest that maps each ID to the exact input, its destination, and the batch ID. This is an application design recommendation, rather than an API requirement. It lets you recover the request body for a retry without trying to reconstruct it from a result file. The batch ID matters when the same logical item is sent in a later batch.
Read the batch status, then inspect its files
The Batch object has a status. OpenAI lists expired for a batch that did not finish within its completion window; the guide says the available window is 24h. The object also exposes output_file_id, error_file_id, and request_counts with total, completed, and failed fields. Those fields tell you where to look and give you counts to compare with your own records. The guide shows the Batch object and status values.
The expired status does not erase completed work. OpenAI says completed responses remain in the output file when a batch expires. Its guide says the output file contains a line for each successful request, while failed requests have information in the error file. Retrieve every file whose ID is present. Treat a missing file ID as a reason to inspect the Batch object and your request records, rather than as proof that every request in that category succeeded. OpenAI explains both result files and expiry.
Reconcile each input line by custom ID
Build a set of IDs from the original input. Parse the output file and attach each successful response to its matching ID. Parse the error file and attach each error to its matching ID. The guide’s expiry example shows an error line with response: null and error.code: batch_expired. That code identifies a request that missed the window. A failed request with another error needs its own diagnosis. See OpenAI’s expiry example.
Check each returned ID against the manifest. Flag an unknown ID, a duplicate ID, or an ID that appears in both files. Compare the combined set of returned IDs with the input set and the Batch object’s counts. If an input ID has no matching line, leave its state unresolved until you investigate. These checks are safeguards for your reconciliation process. They avoid assigning a result to the wrong input or silently marking a missing response as complete.
For a completed ID, validate the response against the needs of the application before applying it. Then record that the ID has been applied. If the reconciliation job runs again, that record lets it skip an already applied result. This is especially useful when a downstream write has its own retry behavior. It also separates receiving a response from making its effect visible to users.
Retry the work that expired
Once the IDs are classified, make a new batch input file from the original request bodies for IDs whose error code is batch_expired. Keep their link to the original IDs and record the new batch ID. Review other errors separately, since an unchanged request that failed for another reason may fail again. OpenAI specifically says the expired request’s custom_id can be used to retrieve its request data. The guide describes expired requests.
A full rerun can duplicate completed work and spend money on requests that already produced responses. OpenAI says completed requests are charged even when the enclosing batch expires. Selective retry follows from that behavior. The exact downstream risk depends on what your application does with each response, so the application should enforce its own rule for applying a logical result once.
What to do
- Save the input file and a manifest keyed by each unique
custom_idbefore submitting the batch. - When the Batch object reaches
expired, retrieve its available output and error files. - Join both files to the manifest by
custom_id, then check for duplicates, unknown IDs, and missing IDs. - Apply validated completed responses once. Put
batch_expiredrequests into a new batch. Investigate other errors and unresolved IDs before retrying them. - Keep the batch IDs, result classifications, and retry links so a later run can reconcile the same work safely.
The Campfire
No commentsNobody has pulled up a log by this one yet. Be the first to say what you make of it.
Held for the desk. It appears after a look.