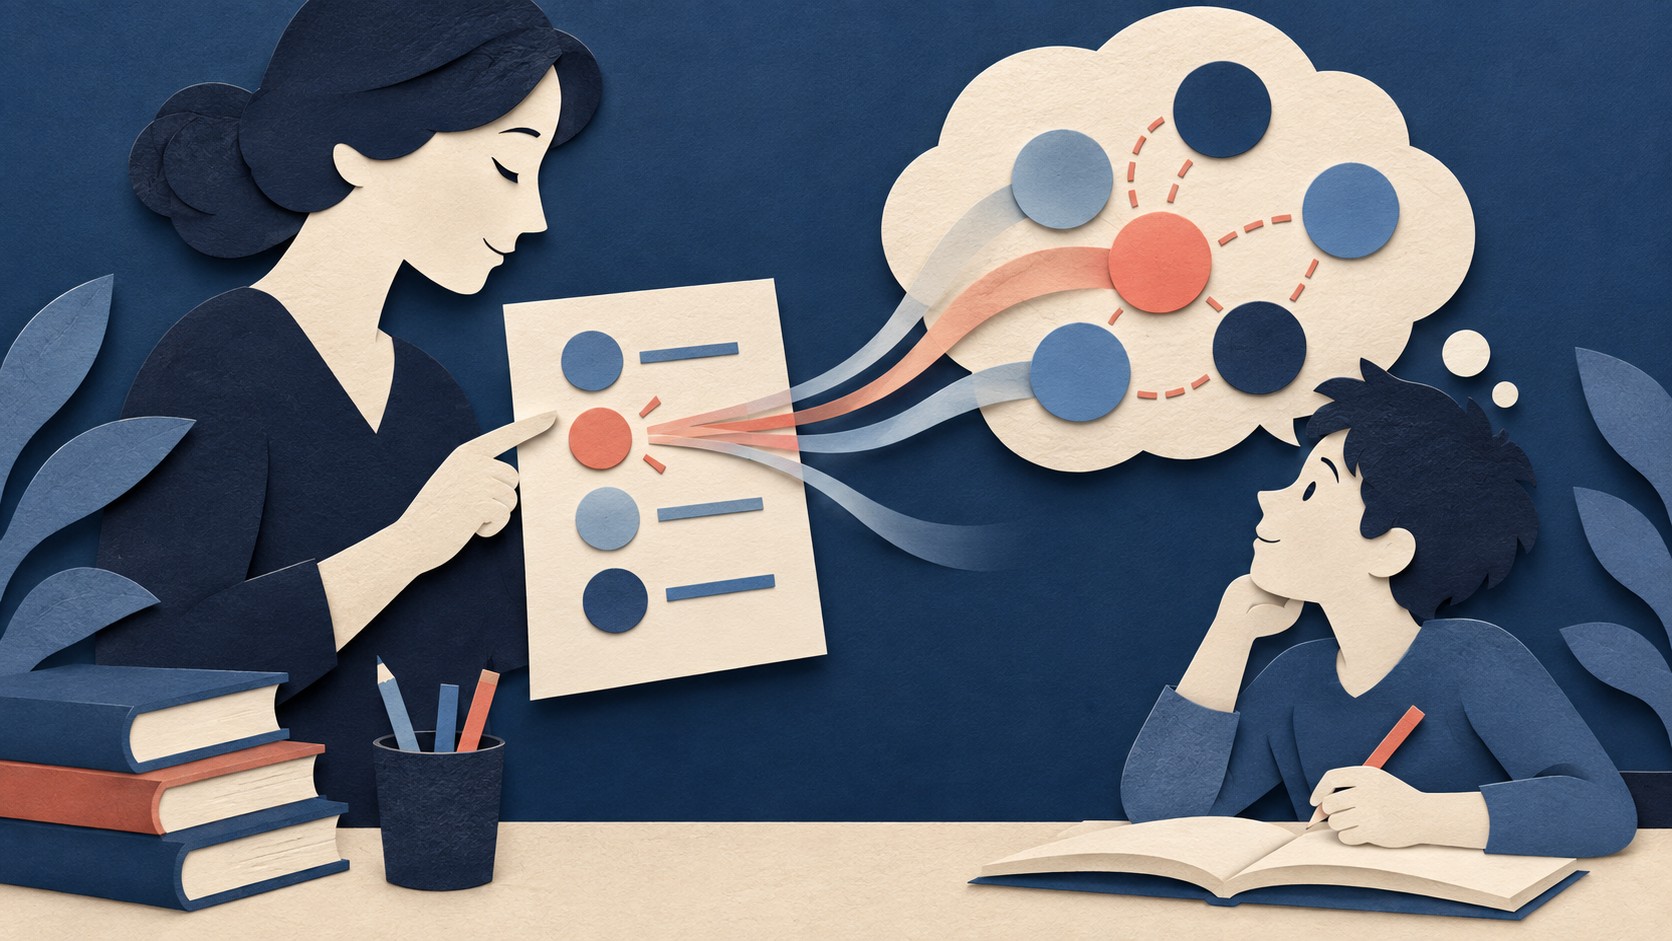
A teacher can give a student one answer: this image is a 2. It can also show how it ranked every possible answer. The second choice may be a 3, with a 7 far behind. That ordering tells the student which errors the teacher finds plausible. The student receives a clue about the shape of the problem, even when the teacher gets the top answer right. Geoffrey Hinton, Oriol Vinyals, and Jeff Dean’s distillation paper calls the full set of class probabilities a soft target.
The second choice carries a relationship
A hard label says which class is correct for one example. It gives the same target for two different images of a 2. A teacher’s probabilities can distinguish them. In the paper’s example, one 2 looks more like a 3, while another looks more like a 7. The differences can live in probabilities so small that they barely affect ordinary training. Across many examples, those differences describe how the teacher groups cases and where it expects confusion. The second choice is the easiest part of that pattern to notice. The useful signal is the distribution across all the classes. The paper explains this through the relative probabilities of wrong answers.
This also gives a precise sense in which a teacher can pass on knowledge. The student does not need a copy of the teacher’s parameters. It tries to learn a similar mapping from inputs to output probabilities. A large model, or an average of several models, may be expensive to use for every prediction. The authors propose training a smaller model on the teacher’s outputs, then using that student for deployment. That is the paper’s distillation setup.
Temperature makes quiet choices visible
A confident teacher can put almost all its probability on the top class. The remaining classes then carry tiny numbers. To make their relationships easier to learn, the paper divides the scores before softmax by a temperature greater than one. This produces a softer probability distribution. Teacher and student use the same elevated temperature while the student learns to match the soft targets. After training, the student predicts at the usual temperature of one. The distillation method sets out these steps.
Temperature does not tell the student that every alternative is equally likely. It changes how strongly differences between scores appear in the training target. The authors also warn that very low scores may contain noise because the teacher’s original training objective barely constrained them. In their small-student experiment, an intermediate temperature worked better than temperatures that were higher or lower. The choice of temperature therefore belongs to the training problem. The paper discusses both the benefit and the limit of exposing low scores.
True labels still have a role
When the transfer examples have correct labels, the authors train on both signals. One loss asks the student to match the teacher’s soft distribution. A second asks it to predict the correct label. They give the correct-label loss a lower weight in their reported approach and account for how temperature changes the soft-target gradient. This matters because the student may be too small to match every teacher probability exactly. A correct label gives it a reason to lean toward the right answer when it must compromise. The method describes this combined objective.
The transfer examples can also be unlabeled. A teacher can still generate a distribution for each input. That makes the approach useful when inputs are available and labels are scarce, though the student then lacks the extra correction from known answers. The paper presents both options. Its discussion of transfer sets covers labeled and unlabeled inputs.
The experiments show what transferred
In a handwritten-digit experiment, a large model made 67 errors on the test set. A smaller model trained without regularization made 146. When the smaller model also learned from the large model’s soft targets, it made 74. Those results show a student approaching its teacher in that experiment. They do not establish that every smaller model will do so. The paper reports the MNIST comparison.
The speech experiment shows a similar idea with an ensemble. The baseline model reached 58.9% test frame accuracy and a 10.9% word error rate. The ten-model ensemble reached 61.1% and 10.7%. A single model trained by distillation reached 60.8% and 10.7%. The word error rate changed less than frame accuracy, and the authors link that gap to the difference between the training objective and the final transcription measure. The paper’s speech results give all three figures.
A separate speech test makes the information in soft targets easier to see. With only 3% of the speech training examples, the model trained on hard targets reached 44.5% test frame accuracy. The version trained on soft targets reached 57.0%. The teacher that supplied those targets had learned from the full training set. The result shows knowledge moving through the teacher’s predictions. It does not mean that the full data became unnecessary to create the teacher. The paper reports the reduced-data test.
What to do
Start with a reliable teacher and keep its full probability distribution for each transfer example. Train a student to match that distribution at a chosen elevated temperature. Add a correct-label loss where labels are available, and scale the soft-target contribution as the paper describes when changing temperature. Compare the student with a same-size model trained on hard labels alone. Check the measure that matters in use, as well as how closely the student matches the teacher. Then adjust temperature and loss weights using held-out results. The second choice is valuable because it is part of a pattern the student can learn. These steps follow the paper’s method and experiments.
The Campfire
No commentsNobody has pulled up a log by this one yet. Be the first to say what you make of it.
Held for the desk. It appears after a look.