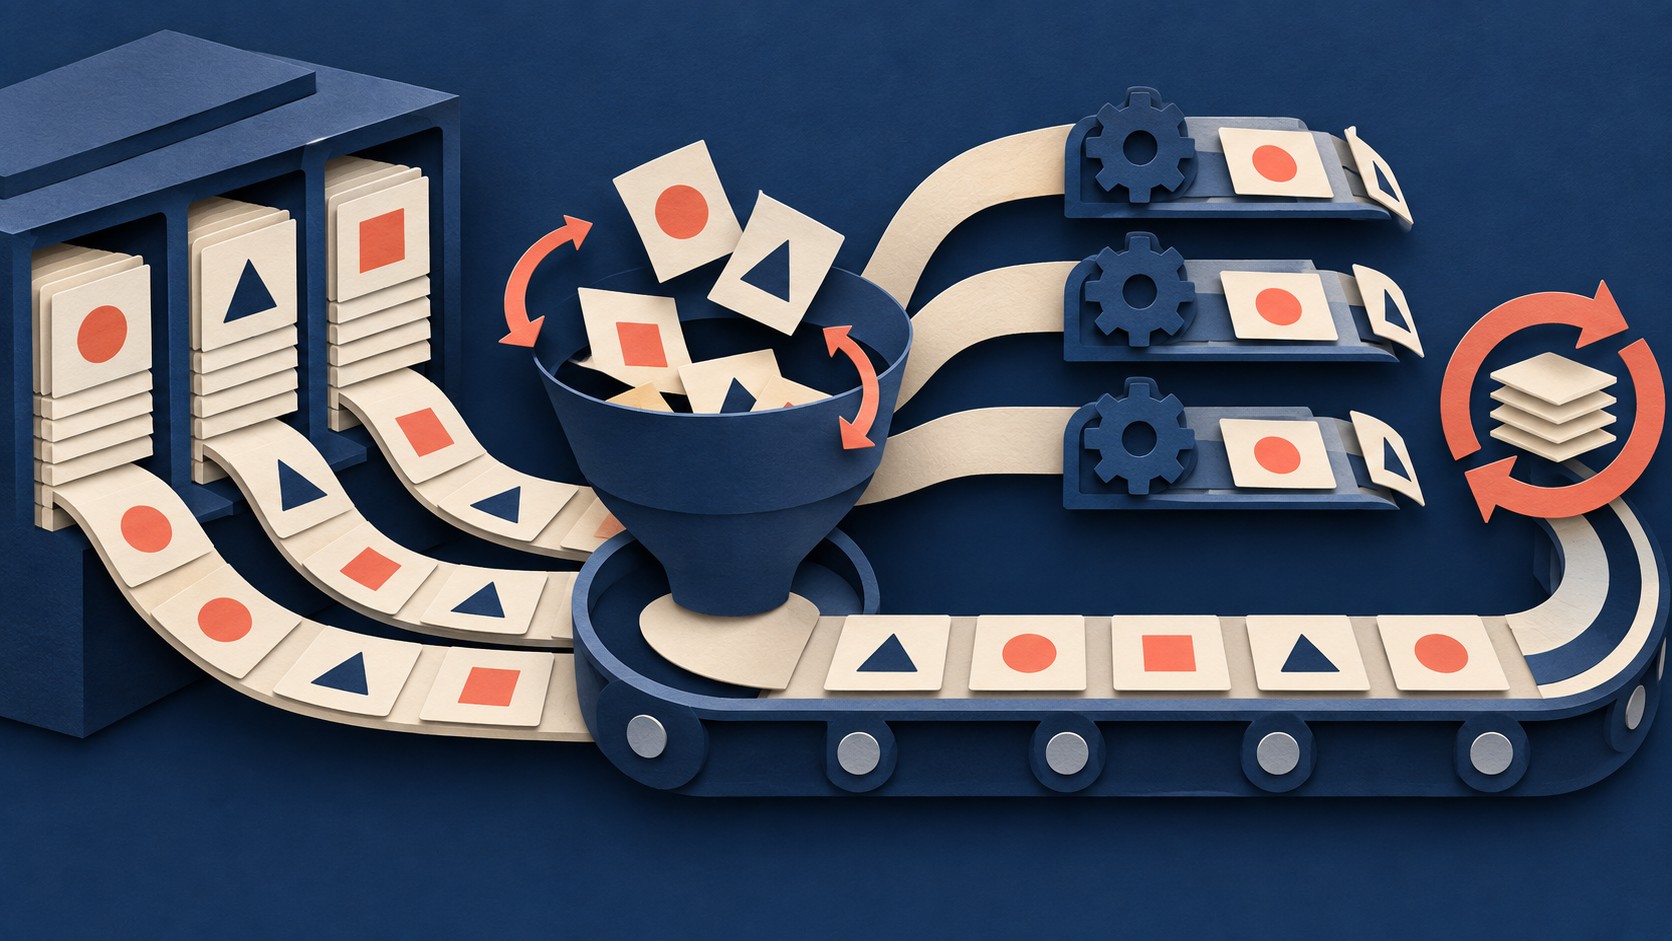
A large training corpus can be useful long before you have room to store it. Hugging Face’s streaming guide shows how to read examples as an iterator with streaming=True. You can inspect records, transform them, and feed them into a training loop without first downloading the full dataset. The same mode can read local files without converting the entire collection to Arrow.
Streaming changes how examples arrive. It also changes how you shuffle, divide work, and resume a run. Those details matter when the source files have an order, such as records grouped by topic or time.
What streaming changes
A regular Hugging Face Dataset supports row lookup by index. A streamed load produces an IterableDataset, which yields examples as you iterate. Reaching a late example means passing through earlier ones. That makes the iterable form useful for sequential training and quick sampling. Work that needs frequent arbitrary row lookup fits a regular dataset better. Hugging Face compares the two types.
The basic call is short:
from datasets import load_dataset

data = load_dataset(
    "HuggingFaceFW/fineweb",
    split="train",
    streaming=True,
)
first = next(iter(data))
This follows the streaming guide’s example. Iteration starts the read. You can also stream local compressed JSONL files with load_dataset("json", data_files=..., streaming=True). For Parquet sources, the guide shows options to select columns or filter rows. Those choices can keep unwanted fields or rows out of the stream.
How the shuffle buffer works
A stream has no general way to fetch any row at random. Hugging Face therefore uses a buffer for IterableDataset.shuffle(). It fills the buffer, draws a random example from its contents, and replaces that example with the next one from the source. The guide shows buffer_size=10_000 as an example and states that the default is 1_000. These are counts of examples. The streaming guide describes the replacement process.
Imagine the source starts with one topic and ends with another. A small buffer can only mix examples that have reached it. Early output still comes from the early part of the source. A larger buffer gives the shuffle more examples to choose from at each step and requires room to hold them. The right size depends on the size of each example and the mixing your training job needs.
The dataset comparison guide calls this an approximate shuffle. A regular Dataset can shuffle its index mapping across the full collection. A streamed dataset cannot use that method because it has no arbitrary row access. If the input is strongly grouped, inspect the output before assuming that a buffer has mixed it enough.
Why shards change the picture
A shard is a piece of a dataset that can be read separately. For a dataset spread across files, those files can supply shards. Hugging Face also describes resharding Parquet data by row group. When a streamed dataset has multiple shards, shuffle() changes their order as well as mixing examples through its buffer. That gives the stream another way to break up the source order. The streaming guide covers shard shuffling and resharding.
Shards also let workers divide loading. The guide shows a locally loaded dataset converted with to_iterable_dataset(num_shards=64), then passed to a PyTorch DataLoader with four workers. In that example, workers receive shards from the shuffled shard list. Inspect num_shards before choosing a worker count. A single shard gives the loader less work to distribute than a collection of shards. See the guide’s worker example.
There is a separate shard(num_shards=..., index=...) operation for selecting one part of an existing iterable dataset. It is useful when you explicitly assign parts of a stream to different jobs. Shard count, shard order, and example order each affect which records a worker sees first.
Plan for passes and restarts
To change the shuffle between epochs, call set_epoch(epoch) on the shuffled dataset before iterating. Hugging Face says the effective seed becomes the initial seed plus the epoch. This lets a training loop use a different order on each pass. The guide includes the loop pattern.
Streaming also changes a restart. An iterable dataset cannot jump straight to an arbitrary row index. It can save and load iteration state with state_dict() and load_state_dict(). The state tracks the current shard and position within it. Resuming skips earlier shards and advances through the current one to the saved position. The guide warns that, when shuffle is active, examples sitting in the shuffle buffer are lost at resume and the buffer refills. A checkpointed training job should account for that change in data order. Hugging Face documents the resume behavior.
Order matters for small inspections too. take(n) and skip(n) fix shard order, so the guide says to shuffle before using them. Apply that order in a quick sample and in the training pipeline.
What to do
- Start with a small streamed inspection. Set
streaming=True, read a few examples, and check that the fields and values suit the task. For local files, pass the file pattern throughdata_files. - Inspect
num_shardsand the original ordering. If the data is grouped, useshuffle(seed=..., buffer_size=...)beforetake()orskip(). Choose a buffer that fits the memory available for actual examples. - Feed the iterable into the training loop or a
DataLoader. If you use workers, check how shards are assigned. Callset_epoch()before each new pass when you want a changed order. - Save iteration state alongside model and optimizer checkpoints if the run must resume. Account for the documented shuffle buffer loss on restart.
These steps follow Hugging Face’s streaming and training guidance. Streaming gives you access to data in sequence without a full local copy. The resulting training order depends on the source layout, shard layout, and buffer you choose.
The Campfire
No commentsNobody has pulled up a log by this one yet. Be the first to say what you make of it.
Held for the desk. It appears after a look.