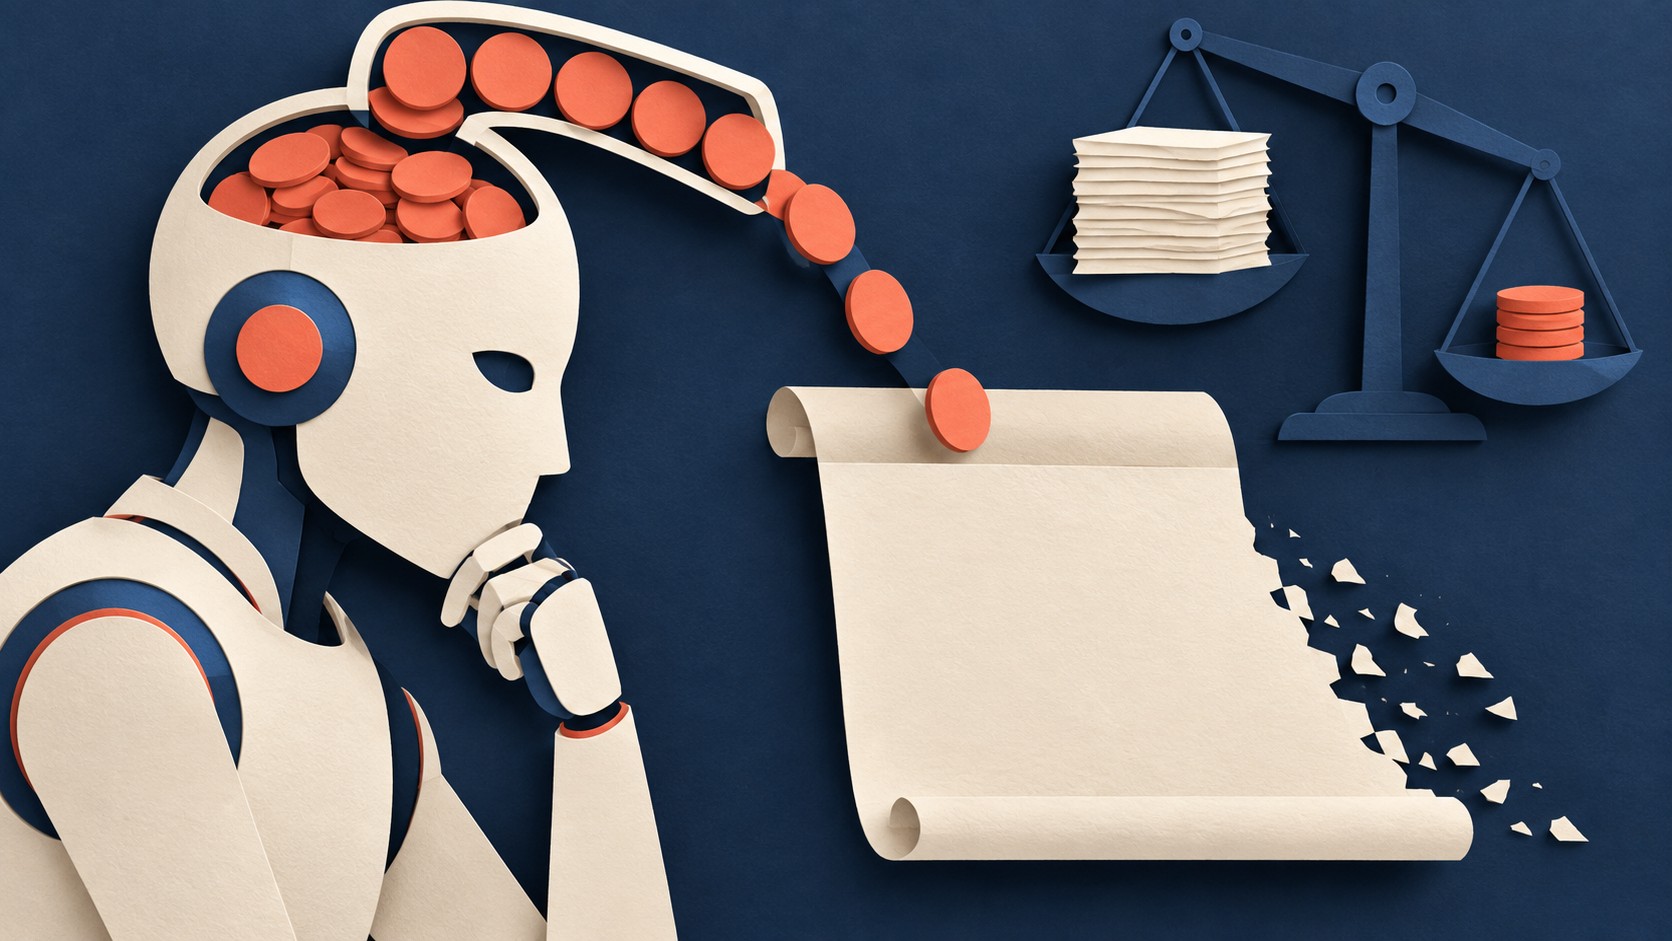
An output cap can sound like a limit on the answer’s length. In Google’s Gemini Interactions API, max_output_tokens limits all generated tokens, including thought tokens. A thinking model reasons internally before responding. The reasoning and the final answer therefore share the same ceiling. Google’s thinking guide explains this limit.
How the answer disappears
max_output_tokens is a hard cutoff. Setting it does not reduce the model’s thinking level. Google says that if the limit is reached during reasoning, the interaction ends with an incomplete status and can return a truncated or empty answer. The thought tokens generated before that point are still billed. Google documents both the cutoff and its billing effect.
Consider an application that sets a small cap because it wants a brief reply. The request still calls for substantial reasoning. The model may spend the available tokens before it reaches the reply. The application then receives no usable answer, despite asking for only a few sentences. This is the failure path described by the shared limit.
What the response can show
The Interactions API reports thought tokens and output tokens in separate usage fields: total_thought_tokens and total_output_tokens. It also represents thoughts and model output as separate steps. Those details can help explain why a response contains little visible text. The thinking guide shows the steps and usage fields.
Thought summaries need careful reading. The API returns the final output by default; summaries can be enabled separately. A thought step may have an empty summary even when a signature is present. An empty summary alone does not establish how many tokens the model spent thinking. Check the usage fields instead. Google describes these summary and usage behaviors.
What to do
Check the interaction status whenever an answer is empty or cut short. Treat incomplete as an unfinished answer, and inspect both token counts. Allow enough output capacity for reasoning and the final text when a complete reply matters.
If the goal is lower cost or latency, Google’s guidance is to lower thinking_level to low or medium instead of setting a small max_output_tokens value. Its best practices also suggest lower thinking levels for simple tasks. See Google’s controls and recommendations. Make the caller handle an empty or incomplete answer explicitly before showing it to a reader.
The Campfire
No commentsNobody has pulled up a log by this one yet. Be the first to say what you make of it.
Held for the desk. It appears after a look.