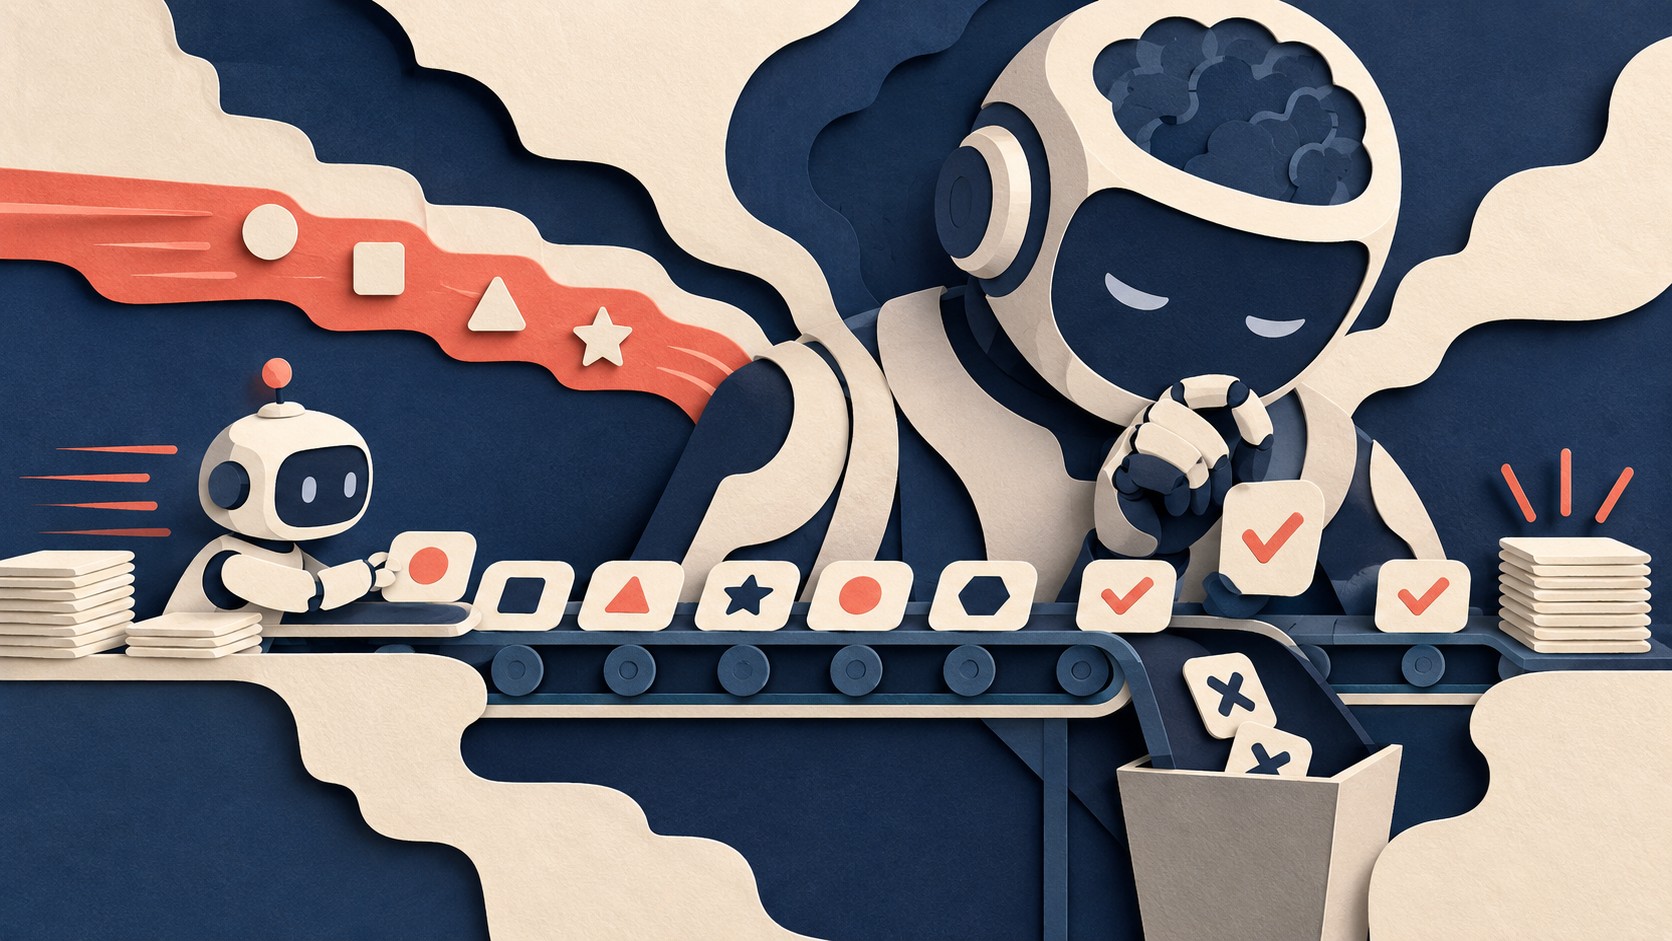
A large language model usually writes a response one token at a time. Each new token depends on the tokens before it, so the model must finish one decoding step before starting the next. That serial work can make a long answer feel slow. The original speculative decoding paper describes a way to reduce those expensive steps: let a faster model draft a short continuation, then ask the large model to check it.
The draft is a proposal. The large model still decides which tokens become part of the answer. This arrangement helps when checking several proposed positions together takes less time than producing those positions one by one.
The draft gives the large model a head start
Call the large model the target and the small one the assistant. The assistant starts from the current text and generates several candidate tokens in sequence. The target then evaluates those candidates together. It can accept a run of candidates before it needs another decoding step. Hugging Face’s assisted decoding guide describes this as one target forward pass that checks the assistant’s draft.
Imagine the assistant proposes the continuation “on the table.” If the target accepts the early pieces, they can enter the answer together. If it rejects a piece, the rest of that draft loses its place, because those later pieces were proposed after the rejected one. The target supplies a corrected continuation, and drafting begins again from the accepted text. This example explains the sequence; it is not a measured output.
The key saving is fewer serial target passes. The target still examines the candidate positions. It simply handles that examination in parallel within a pass. The paper’s algorithm produces at least one accepted or corrected token from each target pass. Several accepted draft tokens can move the answer farther forward.
Verification keeps the target in charge
For a fixed choice of the next token, verification is easy to picture: the target checks whether a proposed token agrees with its own choice. Random sampling needs more care. A candidate that looks plausible to the target cannot simply be kept every time, because that would change how often different answers appear.
The original method uses an acceptance rule based on both models’ probabilities. When it rejects a candidate, it samples a correction from an adjusted target distribution. The authors show that this process preserves the target model’s output distribution. Their derivation is the reason the assistant can help with sampling while the target remains the authority over the result. Matching a distribution does not promise the same random sentence on every run.
That guarantee applies to the standard lossless method. Hugging Face also documents an option that verifies against a mixture of target and draft probabilities. The guide says that option changes the output distribution. It is a separate trade-off from the method explained here.
The extra model has to earn its cost
The assistant takes time to draft. Its guesses also have to survive the target’s checks. A cheap assistant that often agrees with the target can save enough target passes to cover its own work. A slow assistant, or one whose guesses are often rejected, gives back much of that saving. The paper’s runtime analysis makes both assistant cost and acceptance rate part of the speed calculation.
Smaller is therefore useful, but size alone does not settle the choice. In the paper’s T5 experiments, the smallest tested assistant gave the best speedup, even though larger assistants had higher acceptance rates. The authors measured that result for specific translation and summarization tasks, with single-item batches on one accelerator. It is evidence for balancing cost against agreement, not a speed promise for another model or machine. See the experimental setup and results.
Hardware matters too. The paper explains that speculative decoding can reduce waiting when memory movement limits the target and extra computation is available. It can increase the total arithmetic work. When spare computing capacity is scarce, that added work can erase the latency gain. Short generations also leave fewer target steps to save, a limit in the paper’s runtime model. The discussion and analysis make speed a workload question.
Software support sets practical boundaries
Hugging Face’s guide says its ordinary speculative decoding works best when the assistant is much smaller and shares the target’s tokenizer. It supports greedy generation and sampling, but its documented implementation does not support batched inputs. The same guide describes a separate route for assistants with different tokenizers, using extra re-encoding and alignment. Those details matter when choosing a model pair and an inference setup. The implementation guide lists the options.
What to do
First, measure the target alone on the prompts and output lengths you actually serve. Keep that baseline for the same hardware and generation settings. Next, choose a much smaller assistant that uses the same tokenizer where possible. Hugging Face shows how to pass it as assistant_model to generate(). Its example is a starting point for a single-input trial.
Then compare end-to-end generation time with the assistant enabled. Include the assistant’s loading and memory needs if they matter to your deployment. Watch how many proposed tokens the target accepts, and compare short answers with long ones. These checks follow the paper’s cost and acceptance analysis. Keep the assistant only where the measured latency improvement is worth the added resources.
The Campfire
No commentsNobody has pulled up a log by this one yet. Be the first to say what you make of it.
Held for the desk. It appears after a look.