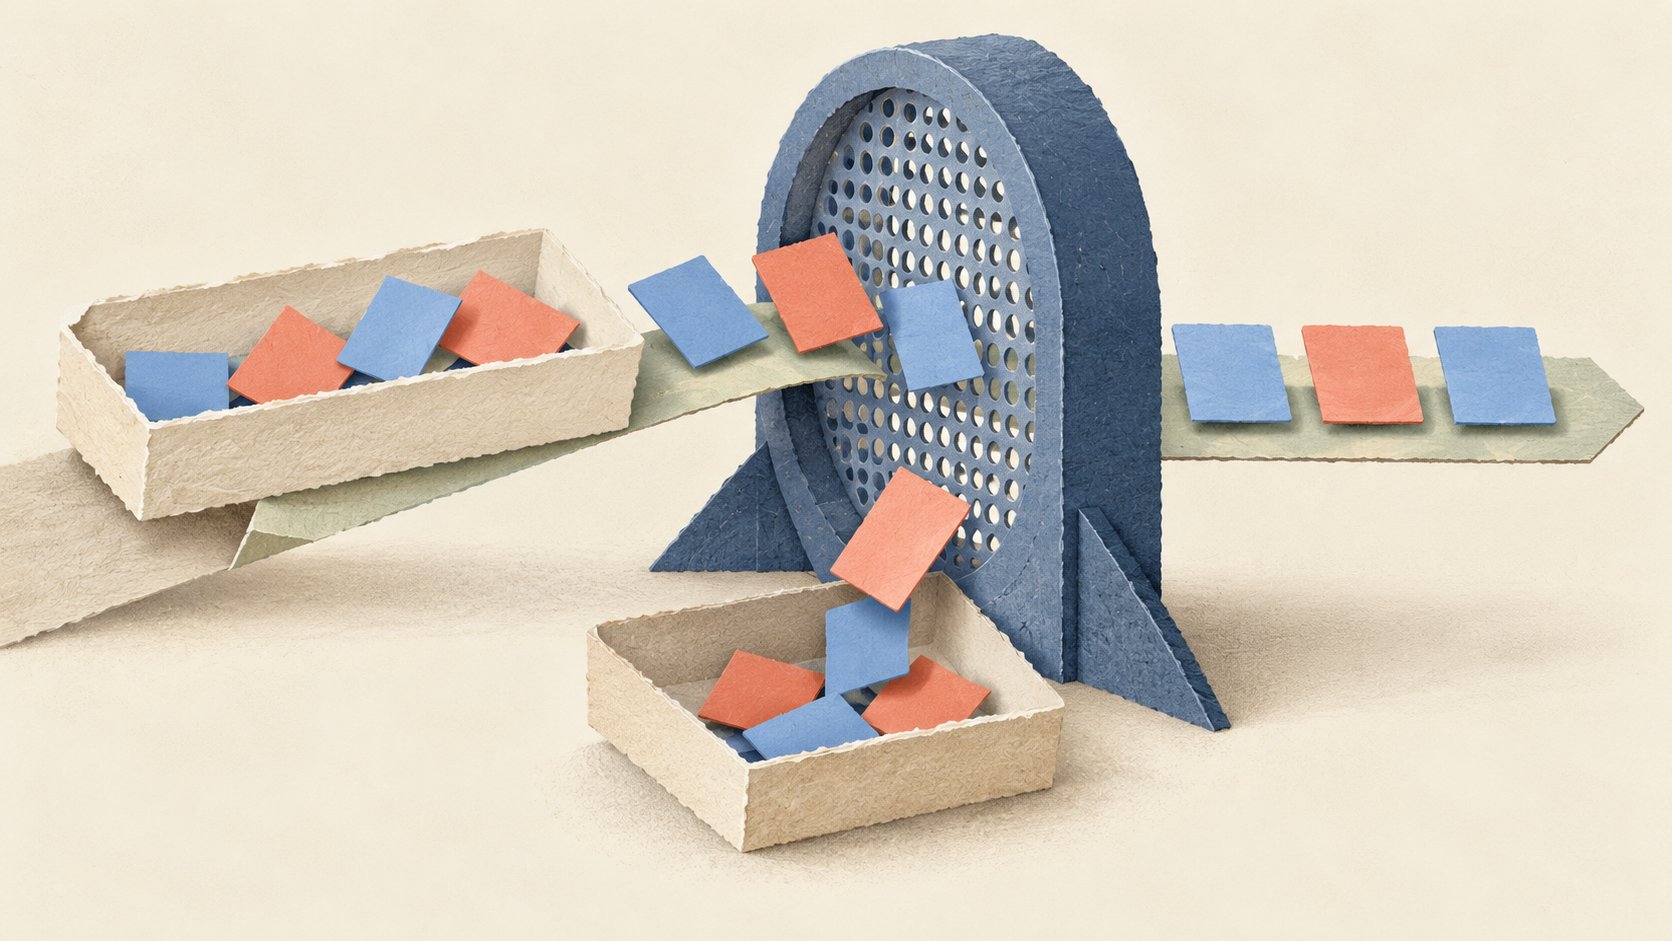
A language model usually writes one token at a time. Each new token becomes part of the context for the next step. That serial loop can make a long answer feel slow, even when the model has ample computing power. Speculative decoding gives the model a head start: a faster draft component proposes several tokens, and the main model checks them together before any proposal becomes output. The main model still decides what the reader receives. vLLM’s explanation of the decoding loop lays out both paths.
The draft waits for approval
Think of the draft as a suggested continuation. It uses the text already accepted and proposes what might come next. The larger model, called the target, evaluates those proposed positions in one verification pass. The check follows the proposed sequence from left to right. Accepted tokens become part of the answer. At the first rejection, later tokens in that draft are discarded because the output now follows a different continuation. The target supplies the next token, and drafting can begin again from the accepted text. The Speculators documentation describes the draft-then-verify step, vLLM’s worked example shows what happens at a rejection, and the original paper shows the target still yields at least one new token per run.
The draft does useful work only when its suggestions survive. If several do, one target verification step can advance the answer by several tokens. If an early suggestion fails, most of the draft is thrown away. The target remains in the loop on every round. The original speculative decoding paper describes this as a way to reduce serial calls to the target model while preserving its output distribution.
The speed comes from fewer waits
The gain is about the time spent waiting for successive target steps. A draft adds computation, and checking several positions also takes work. Yet a target model can evaluate those positions together. When enough proposed tokens are accepted, that combined work can take less time than asking the target to produce each token in a separate round. The original paper’s analysis ties the gain to both draft acceptance and the cost of running the draft. It also notes that the method can increase total arithmetic work while reducing elapsed decoding time. Read the paper’s runtime analysis.
That trade matters for a service handling many requests. A setting that helps one waiting reader may behave differently when the machine is busy. vLLM presents speculative decoding as useful for certain memory-bound workloads and says real gains depend on the model, traffic, hardware, and sampling settings. Its method guide treats those conditions as part of choosing a configuration.
Exactness has a precise meaning
For ordinary sampling, verification is more careful than asking whether the draft guessed the target’s favorite token. The acceptance rule compares the draft and target probabilities. After a rejection, it samples a replacement from an adjusted distribution. Those steps make the resulting token distribution match the target model’s distribution in the algorithm described by the original paper. A draft can therefore help choose a token without getting authority over the final probability of that token.
“Same distribution” does not promise identical text in every sampled run. Sampling can produce different valid continuations. vLLM also notes that floating-point precision, batch size, and unstable token log probabilities can cause differences between runs. Its losslessness guide distinguishes the theoretical guarantee from those practical sources of variation. The useful promise is that the draft need not lower the target’s intended sampling quality to save time.
A longer draft can waste work
It is tempting to ask the small model to predict farther ahead. Later proposals offer more chances to advance in one verification pass. They also cost time to produce and check. If a token near the start is rejected, everything after it is discarded. In vLLM’s workload study, the best proposal length varied across models and tasks. More accepted tokens did not automatically mean better end-to-end throughput, since the draft itself has a cost.
The draft need not always be a separate, general-purpose small model. vLLM documents draft models, auxiliary prediction components, and methods that reuse patterns in existing text. They share the proposal-and-verification idea, while differing in how they produce candidates and what extra work they require. vLLM’s method guide is a useful map of those options.
What to do
If you run an inference service, begin with a baseline using your actual prompts, output lengths, and traffic pattern. Record how long users wait between output tokens and how much output the service produces. Then try a supported drafting method with a short proposal length. Compare the complete request, including the cost of drafting and verification, with the baseline. vLLM’s method guide points to a benchmark script and CLI for reproducible measurements in your environment, and its blog study recommends representative workloads and end-to-end measurements.
Watch how many proposed tokens are accepted, especially toward the end of each draft. Try a few proposal lengths instead of assuming the longest wins. Keep a setting only when it improves the measure your users care about under their real traffic. If acceptance is poor or the draft is expensive, a plain target-model run may be faster. Those checks follow the vLLM study’s tuning guidance.
The Campfire
No commentsNobody has pulled up a log by this one yet. Be the first to say what you make of it.
Held for the desk. It appears after a look.