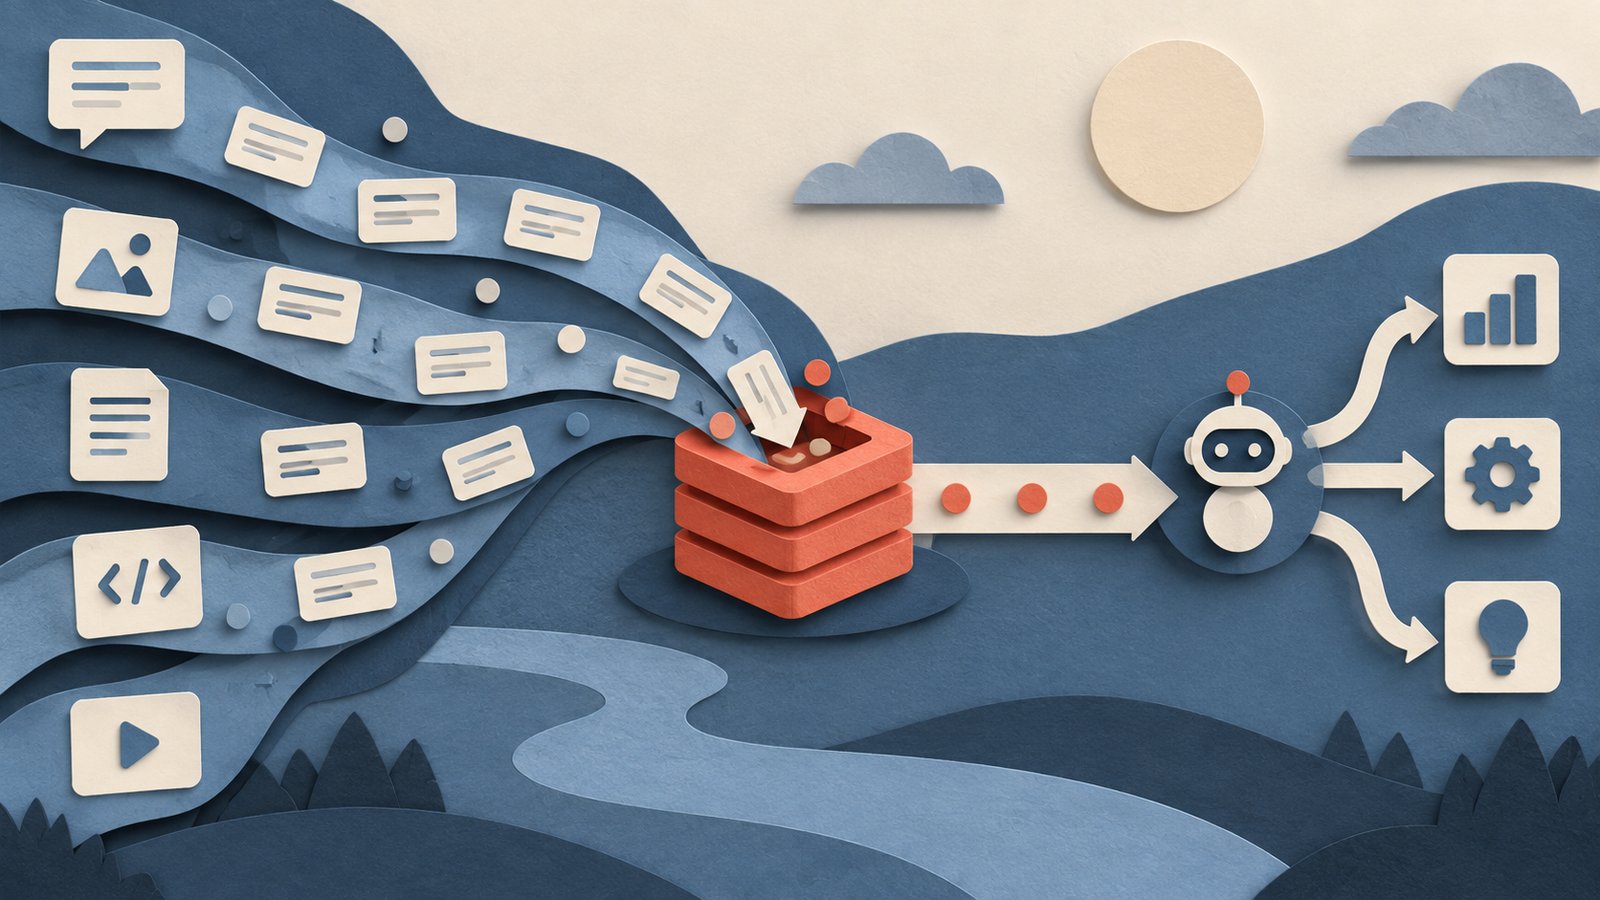
Redis is useful in an AI application when several parts of a request need to share small pieces of state. A gateway may count a user’s model calls, workers may claim queued agent jobs, and a chat service may load the latest turns. Redis can serve each role with data structures and expiration rules, while a search index can also find similar vectors.
That range can simplify an architecture, but it can also concentrate failure. Before putting prompts, quotas, job state and session memory in one deployment, decide which data can be rebuilt, which must survive failures, and what happens when Redis is unavailable. Redis can act as a shared state layer; it does not make those application decisions for you.
Cache exact model responses first
The simplest model cache maps an exact request key to a previous response. A key can incorporate the normalized prompt, model identifier, system prompt version and relevant generation settings. Include every input that could change the answer. If the application has tenant-specific data or permissions, scope the key to that boundary too.
Give entries a time-to-live (TTL), the period after which Redis expires a key. A TTL limits how long an answer can linger after the model, policy or source data changes. It is a freshness bound, not a correctness guarantee. Keep the cache disposable: a miss should fall back to the normal model path, and a cache loss should not erase the only copy of user data.
For generated answers, cache only when the response is safe to reuse. An answer that depends on account access, current inventory or private conversation context should not be shared just because its prompt resembles another user’s. Treat cache key design as part of authorization design.
Semantic caching trades certainty for reuse
An exact cache only hits when a key matches. A semantic cache embeds an incoming prompt and searches for stored prompts with nearby vectors. If a candidate passes a similarity threshold, the application can return its stored response without calling the model. Redis’s semantic-cache guide describes storing the prompt, embedding, response and metadata together, then combining vector lookup with metadata filters and expiration.
Similarity is not equivalence. Redis’s LangCache concepts documentation explicitly describes the risk: a false-positive match may answer a different question. “How do I reset my password?” and “How do I reset another user’s password?” can be close in wording while requiring different access decisions. Version the model and knowledge context, and filter by tenant, locale and safety scope before considering a hit. Start with a conservative threshold, inspect matched pairs, and measure wrong-answer rates alongside cache hits. When the cost of a mistaken answer is high, skip semantic response reuse.
Rate limits and token budgets solve different problems
OpenAI’s API pricing lists separate rates for input and output tokens on many models. A request-count limit can stop a client from making too many calls, but it does not account for different costs per call. Put per-user, per-tenant or per-model request limits at the gateway, and estimate token costs separately against a budget.
Redis can provide shared counters for application instances. Its rate-limiter documentation shows fixed-window counters and token-bucket patterns, with Lua scripts for atomic read-and-update decisions. Atomicity matters when concurrent requests could otherwise all observe the same remaining allowance. Decide what the service does when Redis is unreachable: rejecting model calls prevents additional calls during the outage, while allowing calls favors availability and can exceed the budget. That choice belongs in the product’s cost policy.
Streams can coordinate agent jobs
Agents often perform slow work that should outlive the request that started it: retrieve documents, call tools, wait for approval or generate a long report. A Redis Stream can hold ordered job entries while a consumer group distributes work among workers. Redis’s streaming documentation describes pending entries and explicit acknowledgements: a worker acknowledges a message after processing, and unacknowledged work can be inspected and reclaimed.
This is a useful coordination primitive, not a promise that a job runs exactly once. A worker can finish an external action and crash before acknowledging its entry, so another worker may repeat the action. Give jobs stable identifiers, make side effects idempotent where possible, record terminal status, and decide how retries and permanently failing jobs are handled. Set retention and trimming rules so history does not grow without bound, while allowing workers to finish or recover pending jobs before their entries are trimmed. If the job is valuable business data, persist its authoritative state in a durable store as well.
Keep short-term conversation state bounded
For chat sessions, Redis hashes can hold recent turns and metadata under a conversation identifier; expiration can clear inactive sessions. Redis’s session-store guide describes shared per-user state with TTLs across stateless application servers. An agent can similarly load a short working window, append a turn and expire it after inactivity.
Do not confuse session memory with long-term memory. Recent turns are operational context, not a reliable archive or a user-approved profile. Bound the number or size of stored turns, avoid placing secrets in prompts without a reason, and give users a deletion path if the application stores personal conversation data. Store durable preferences or records in the system that owns them, then retrieve only the relevant subset for a model call.
Vector search can sit beside application state
Redis Search supports vector search as well as full-text queries over indexed hash and JSON documents, according to its search documentation. That lets an application retrieve semantically similar documents and filter on metadata in the same service that holds cache entries or session state. This can be convenient for a moderate retrieval workload, especially when one operational system is preferable to several.
Vector search does not make Redis a complete retrieval pipeline. Your application still chooses an embedding model, chunks and updates documents, applies access controls, assembles context and evaluates retrieval quality. Measure recall and latency on your own corpus. Compare the memory and operational cost with a dedicated vector database or your existing search engine before moving a large corpus into Redis.
Check the exact Redis license and distribution
The word “Redis” can mean different releases and distributions, so check the license attached to the server you deploy. Redis announced that, starting with Redis 7.4, it would use the Redis Source Available License version 2 (RSALv2) or Server Side Public License version 1 (SSPLv1), replacing the three-clause Berkeley Software Distribution (BSD) license for new releases; the March 2024 announcement says the change was not retroactive. In response, the Linux Foundation announced Valkey as a BSD-licensed continuation starting from Redis 7.2.4 (launch announcement). Redis later added the GNU Affero General Public License version 3 (AGPLv3) as an option beginning with Redis 8, according to Redis’s licensing update.
As of September 2026, those are distinct licensing paths, and compatibility does not make their licenses interchangeable. Read the license for the exact source, image or managed service you plan to use, especially if you redistribute it or offer it as a service. The Valkey migration guide describes compatibility with Redis Open Source 7.2 and earlier; check the target’s supported commands and modules for the features your application needs.
Choose Redis for a specific state problem
Start with one measured need: repeated exact prompts, shared request quotas, a worker queue, short-lived conversation state or filtered vector retrieval. Add a TTL or retention rule, define behavior during Redis failure, and measure correctness as well as latency and cost. Keep durable records and authorization decisions in their owning systems. If Redis solves that concrete problem within your license and memory budget, expand from there; if the main requirement is durable workflow orchestration or large-scale vector retrieval, compare systems built around those guarantees before committing.
The Campfire
No commentsNobody has pulled up a log by this one yet. Be the first to say what you make of it.
Held for the desk. It appears after a look.