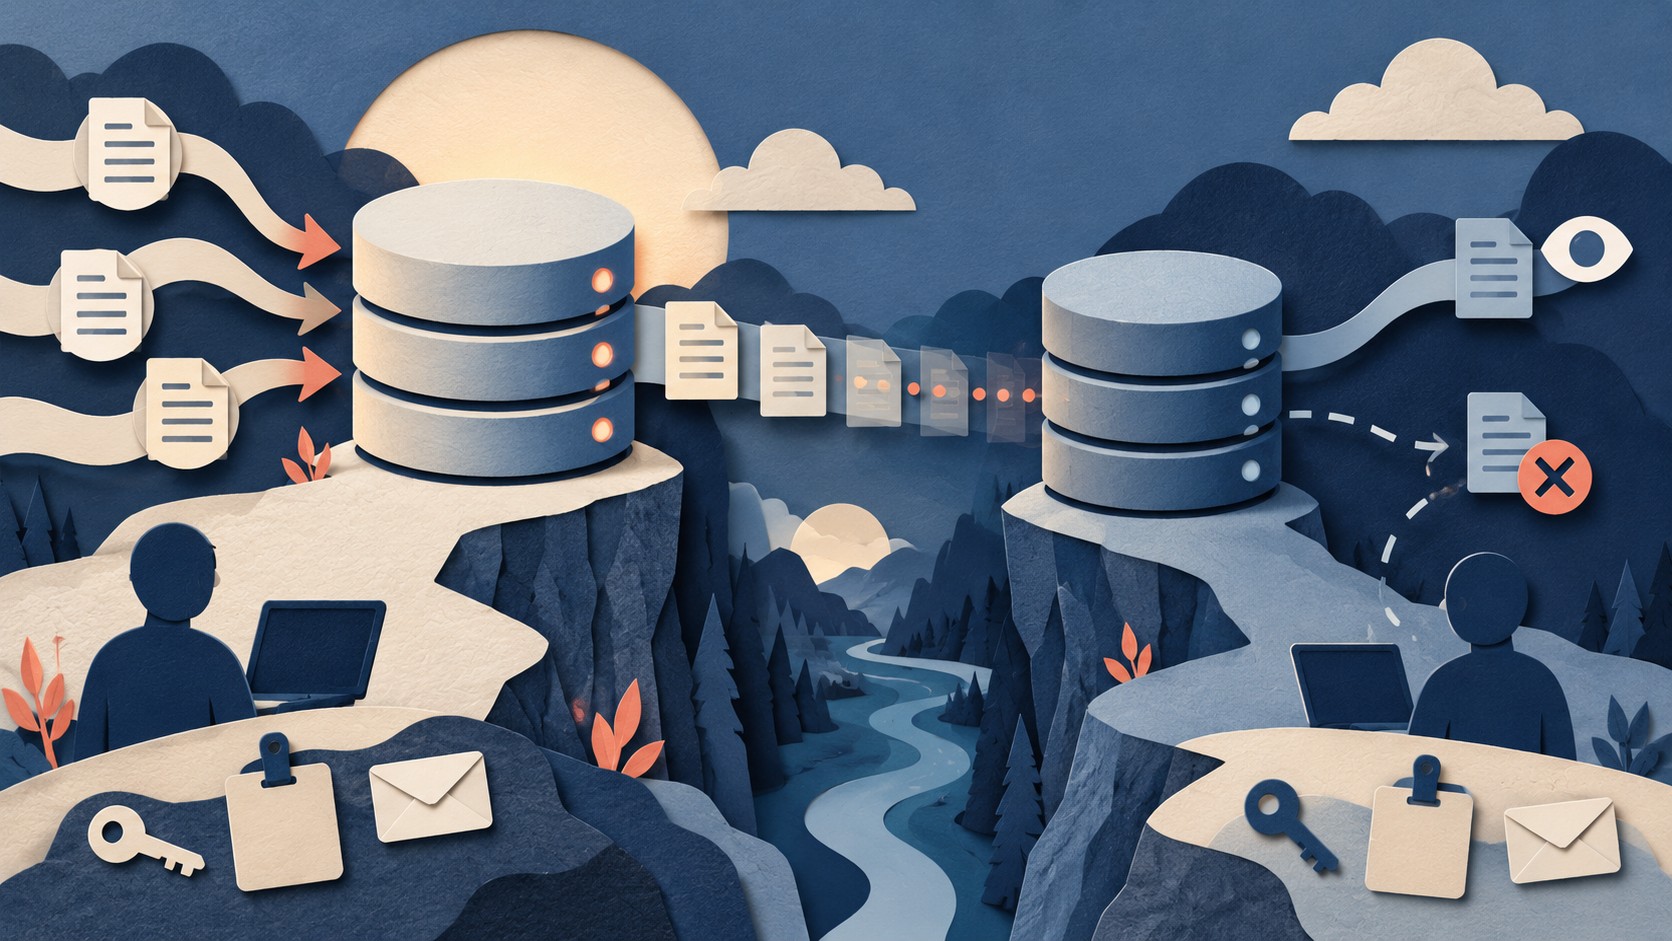
A read replica looks like the same database. It answers the same queries, over the same protocol, with the same schema. That is the illusion, and it is a useful one, which is why it is so easy to forget that a replica is a different thing with different rules.
The PostgreSQL hot standby documentation states the two facts plainly, and everything else follows from them.
Eventually consistent
The data on the standby is eventually consistent with the primary. The data takes some time to arrive from the primary server, so there is a measurable delay between them. Running the same query nearly simultaneously on both servers might therefore return different results. A write you committed on the primary is not visible on the replica until its commit record has been replayed there. Once it is replayed, the change becomes visible to any new snapshot taken on the standby. Whether a running transaction sees it depends on its isolation level: at the default READ COMMITTED, each query takes a fresh snapshot and will see the replayed change, while a transaction at REPEATABLE READ keeps the snapshot it started with and will not. The transaction isolation chapter spells out that distinction, and the hot standby caveats note that the SERIALIZABLE level is not available on a standby, so attempting it there errors.
Strictly read-only
Every connection to a hot standby is strictly read-only. Writes fail. DML and DDL both produce errors. You cannot insert, update, delete, create, alter, or even write a temporary table. The database looks the same, and then your INSERT returns an error you did not expect, because the replica was never going to accept it.
What that means for application code
Those two facts produce most of the pain in practice. Code that reads its own writes will see them on the primary but miss them on the replica. A service that writes a row, then reads it back from a replica to confirm, can get an empty result through no fault of its own. A caching layer that warms itself from a replica can hold stale values, and its own refresh or expiry policy decides how long, which has nothing to do with the replication lag.
Queries can be cancelled
There is a third, less obvious property worth knowing before you route traffic: standby queries can be cancelled for reasons that have nothing to do with the query itself.
Because the primary and standby are loosely connected, actions on the primary can conflict with queries running on the standby. A DROP TABLE on the primary conflicts with a query reading that table on the standby. A vacuum cleanup record conflicts with a transaction whose snapshot still sees the rows being removed. On the primary, these conflicts resolve by waiting. On the standby, the WAL record already happened on the primary, so the standby must eventually apply it. It will wait for the conflicting query up to a configured delay before cancelling it.
PostgreSQL manages this with two delay settings, max_standby_archive_delay and max_standby_streaming_delay, which cap how long WAL application will wait for a conflicting query. Once the delay is exceeded, the query is cancelled. The documentation is blunt about the consequence: tables that are regularly and heavily updated on the primary will quickly cause cancellation of longer-running queries on the standby. A long analytical query against a replica that is also catching a heavy write load is a cancellation waiting to happen.
The documentation also names the tradeoffs. Setting hot_standby_feedback prevents the vacuum cleanup conflicts, but it delays dead-row cleanup on the primary, which can cause table bloat. Long delays let long queries finish but let the replica fall behind. Short delays keep the replica close to the primary but cancel queries more aggressively.
What to do
Treat a replica as a different service with a lag. Do not read your own writes from it. Do not assume a value you just wrote is there. Do not put queries on it that cannot tolerate being cancelled, unless you have sized the delay settings for that.
Treat it as read-only at the code level, just as it is at the database level. A write that fails on the replica is a routing bug, and it is easier to catch before it ships than after.
When you do route reads to it, know what you are trading. You are offloading load and buying failover, and paying in staleness, read-only constraints, and the possibility that a long query gets cancelled mid-flight. That is a fine trade when the reads are tolerant of all three, and a bad one when they are not.
The replica is a promise with different terms, and most of the trouble comes from treating its terms as if they were the primary’s.
The Campfire
No commentsNobody has pulled up a log by this one yet. Be the first to say what you make of it.
Held for the desk. It appears after a look.