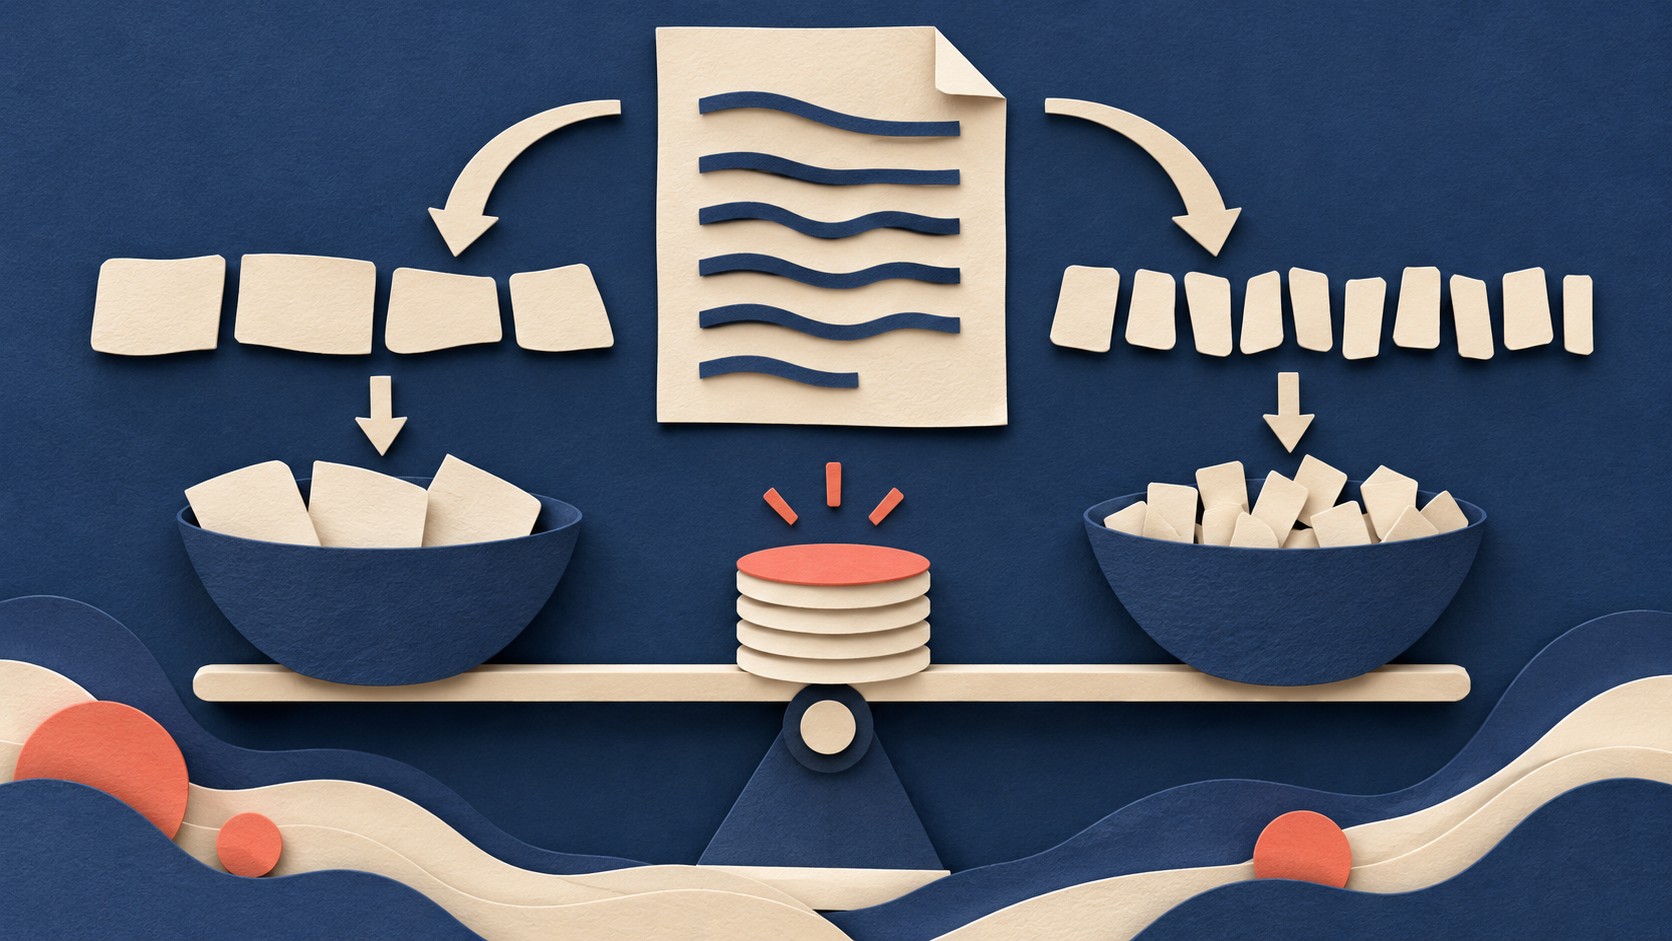
Perplexity looks like a single number for a model’s grip on a passage. The number has a unit: the token. Change where the token boundaries fall, and the score changes meaning. That matters when two language models read the same visible text through different tokenizers. Hugging Face’s perplexity guide states that tokenization directly affects the metric.
What perplexity measures
For an autoregressive language model, each next token receives a probability given earlier tokens. Perplexity takes the average negative log probability over the scored tokens and then exponentiates it. Lower perplexity means the model assigned more probability to those particular token predictions, under that evaluation setup. The score is an average per token. It is not a probability of the entire passage. Hugging Face also notes that the usual definition does not directly apply to masked language models such as BERT. Its guide gives the definition and scope.
The word “token” can hide a large choice. A tokenizer may keep a stretch of text together or split it into smaller pieces. Either way, the model is asked to predict the resulting sequence, one token at a time. The length of that sequence becomes the denominator of the average. The conditional predictions also change because each boundary changes what counts as the next item. These consequences follow from the token-based definition in the Hugging Face guide.
How token boundaries change the comparison
Imagine two models scoring the same written sentence. One tokenizer represents a common expression with a single token. Another breaks it into several pieces. The first model makes one prediction for that expression. The second makes several predictions, each with a different preceding context. Averaging those losses over different numbers of tokens gives scores in different units of prediction. A smaller token perplexity can therefore reflect the segmentation as well as the model’s fit to the text. The Byte Latent Transformer paper puts the comparison rule plainly: perplexity is meaningful in the context of a fixed tokenizer.
Keeping the visible sentence fixed does not remove that difference. A report that says only “perplexity” leaves out the unit that was averaged. Even a shared test corpus is insufficient if the tokenizers divide it differently. The score may still be useful within one fixed model and tokenizer setup, for example when comparing checkpoints on the same held-out text with the same scoring procedure. Across tokenizers, the raw values need more context. This follows from the definition and the fixed-tokenizer caveat.
The scoring window also matters
Tokenization is only one source of variation. A finite-context model cannot always condition on every earlier token in a long passage. Hugging Face explains that splitting text into separate chunks gives many predictions little preceding context and often raises perplexity. A sliding window gives more context. A strided window trades some of that precision for fewer forward passes. Different context windows or strides can move a score even if the model, tokenizer, and text are unchanged. The guide describes these evaluation choices.
The set of scored positions matters too. In a sliding window, some tokens are supplied only as context. Counting their loss again would double count overlapping positions. The Hugging Face example masks those context-only targets. For a comparison, record how much text was scored, which positions were excluded, and how the context was supplied. Otherwise a difference in procedure can be mistaken for a difference in model quality.
A byte-based unit helps
When tokenizers differ, a shared unit can make likelihood results easier to compare. Bits per byte divides the total negative log likelihood, converted to bits, by the number of bytes in the evaluated text. The Byte Latent Transformer paper uses this measure when comparing byte and token-level models. Its appendix gives the calculation and explains why it reports the byte-based measure instead of token perplexity across those models.
The same raw text and byte encoding must be used for that denominator to match. The scoring setup still matters. A byte-based result cannot repair a changed corpus, inconsistent handling of context, or different excluded positions. It also says little by itself about whether a model will perform well on a task that requires understanding or generation. In a study of language models for Nepali, the authors compared tokenization strategies and found that their task results did not follow perplexity alone. That result concerns their study, and it is a useful reminder to evaluate the behavior that matters.
What to do
Use the same held-out text for every model. Keep its formatting and byte encoding fixed. Score each model with its own tokenizer, but save the token count, the summed negative log likelihood, the scored positions, and the context-window procedure. Report token perplexity with the tokenizer named. When tokenizers differ, add bits per byte on the same bytes, using the total loss and byte count described in the Byte Latent Transformer paper. Compare the byte-based results under the same evaluation protocol, then check a task-specific measure before making a claim about usefulness. A perplexity table can be informative when its units and scoring rules travel with the numbers.
The Campfire
No commentsNobody has pulled up a log by this one yet. Be the first to say what you make of it.
Held for the desk. It appears after a look.