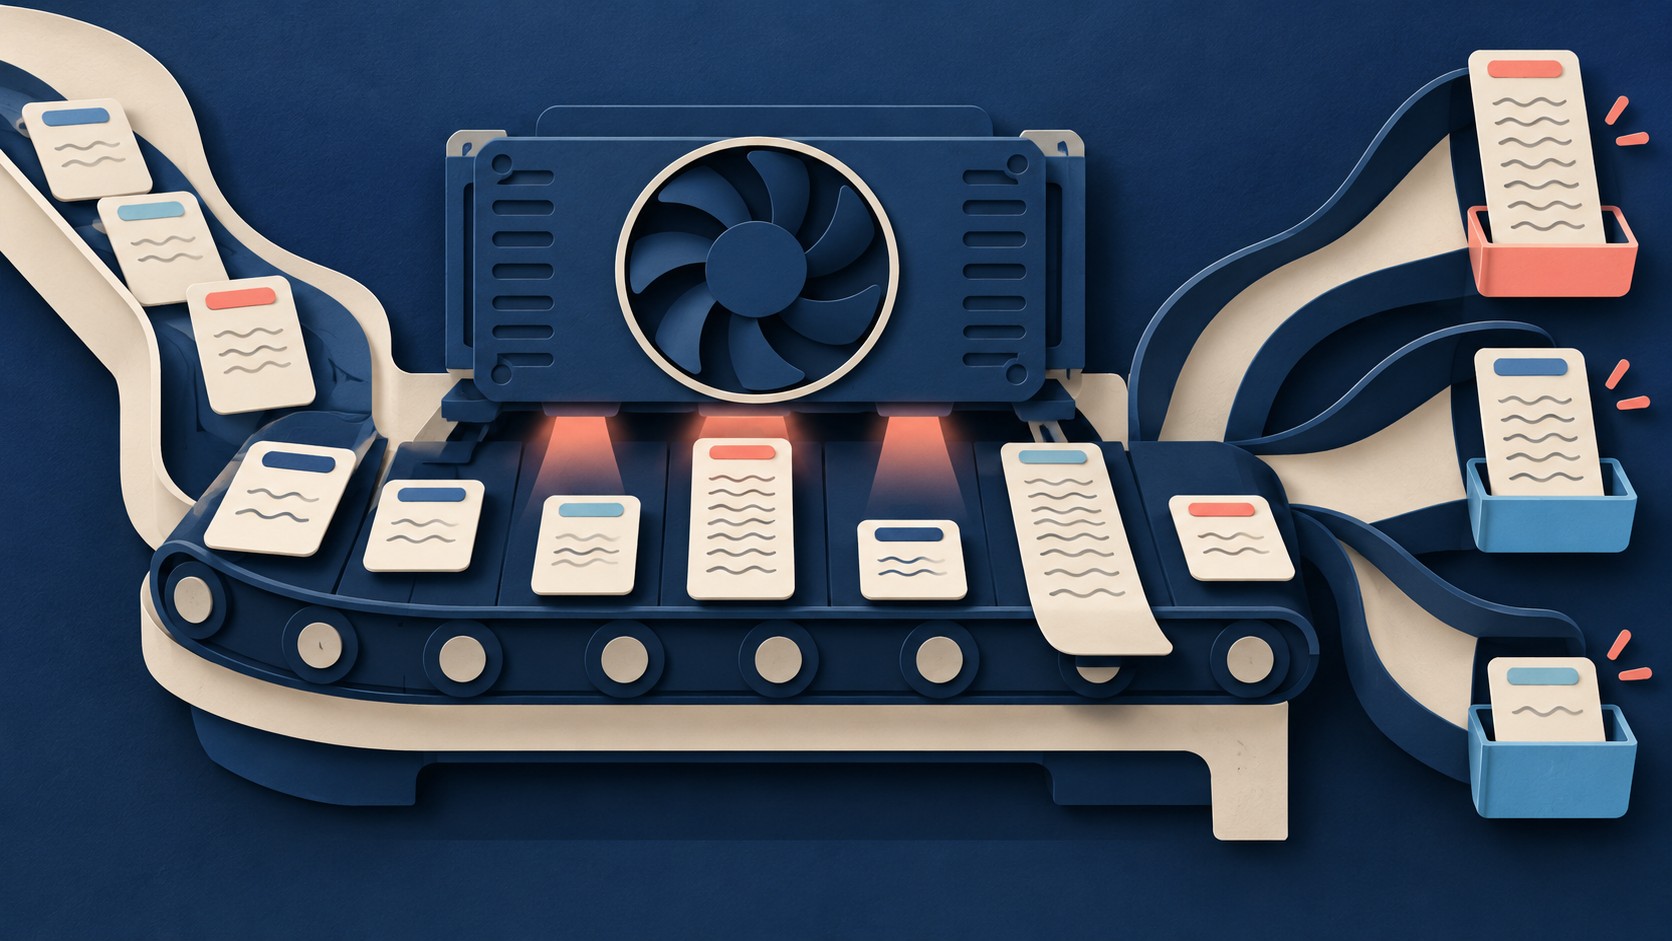
A model serving many people receives requests that take different amounts of work. One person may ask for a brief answer. Another may send a long prompt and request a detailed response. If both enter a fixed batch, the shorter request can finish while the longer one keeps the batch occupied. A waiting request must then wait for the batch to end. Hugging Face’s architecture guide describes this as a source of idle GPU time between batches.
Continuous batching changes when the serving system can admit work. At each generation step, its scheduler checks which requests have finished. It can remove those requests and bring waiting ones into the available space while other responses continue. That is the central idea behind the Transformers continuous batching documentation.
A batch can change while it runs
Think of the batch as a group whose membership is checked after each step of text generation. A short response leaves when it is complete. A longer response stays. If resources allow it, another request joins the group. The longer response does not have to finish before that new request starts. Hugging Face’s explanation calls this dynamic scheduling.
This matters because generated text arrives piece by piece. After a model processes a prompt, it produces output tokens through repeated generation steps. A fixed group can spend later steps carrying a request that has already finished. Replacing that request gives the next steps useful work. The benefit is clearest when requests have different lengths and there is more work waiting. The first-principles explanation traces how uneven lengths and padding waste work in a conventional batch.
Each request has its own path
A request starts in a queue. The model then processes its prompt, a stage called prefill. Next comes decoding, when the model generates output tokens. Finally, the request finishes and its result becomes available. The architecture guide describes these states and the scheduler’s role in moving requests between them.
A newly admitted request may be processing its prompt while an older request is generating its next token. That mixture makes scheduling more involved than filling an empty slot. The system has to fit the new prompt work alongside the active generation work. If a prompt exceeds the available token budget for a step, the scheduler can process it in chunks across later steps. This lets active responses continue between chunks. Hugging Face documents this as chunked prefill.
The model also needs to retain information from earlier tokens so it can continue each response. A key-value cache stores that information and avoids recomputing it at every step. This saves computation, while consuming memory that must be shared among active requests. Hugging Face’s technical walkthrough explains that tradeoff and how chunked prefill uses cached state.
Admission depends on available resources
A finished request creates an opportunity to admit another one. It does not guarantee immediate admission. The scheduler checks a token budget, cache space, and a cap on requests in each forward pass. A waiting prompt can remain queued when those limits prevent it from fitting. The architecture guide lists these limits and explains the admission checks.
Cache pressure also affects how eagerly new work starts. In the documented Transformers implementation, a safety margin can reserve cache space for requests already generating. When free space falls below that margin, the scheduler holds new prompt work and continues active responses. This is a deliberate scheduling choice: admitting every waiting request can leave too little room for responses that are still growing. The configuration guide describes the margin and its effect.
These constraints explain why continuous batching can improve throughput without promising an instant response for every arrival. A request may still wait in the queue or spend time processing its prompt. Long prompts can compete with ongoing generation for each step’s budget. The architecture guide shows how the scheduler divides that work.
Results can arrive independently
Batch membership and result delivery are separate choices. In Transformers, generate_batch() schedules its supplied prompts and returns after all their requests complete. ContinuousBatchingManager accepts requests as they arrive and lets callers retrieve completed results independently. It also supports streaming partial output. The usage documentation distinguishes these interfaces.
That distinction matters to an application. Continuous scheduling can make better use of the GPU, yet an application that waits for every result before responding still makes its users wait. An interface that returns each result as it becomes available can expose the different finish times that the scheduler already handles. This follows from the behavior of the two documented interfaces.
What to do
Start with the shape of the real workload. Include short and long prompts, short and long requested outputs, and periods when requests arrive while others are running. Compare completed work and response timing under the same model and hardware. The Hugging Face documentation identifies throughput, time to first token, decode latency, and memory use as relevant effects of scheduling choices.
If the application serves responses as they finish, choose an interface that exposes independent results or streaming. If requests wait too long to start, inspect the queue, token budget, and cache pressure before increasing batch limits. A larger prefill budget uses more input-buffer memory and leaves less room for cached request state. The configuration guide spells out that tradeoff.
Finally, test the mixed workload again after changing a limit. The useful outcome is concrete: waiting requests start when resources permit, completed requests leave promptly, and long responses keep making progress. Continuous batching supplies the scheduling mechanism. The workload and resource limits determine how much it helps. The architecture guide shows where those limits enter the decision.
The Campfire
No commentsNobody has pulled up a log by this one yet. Be the first to say what you make of it.
Held for the desk. It appears after a look.