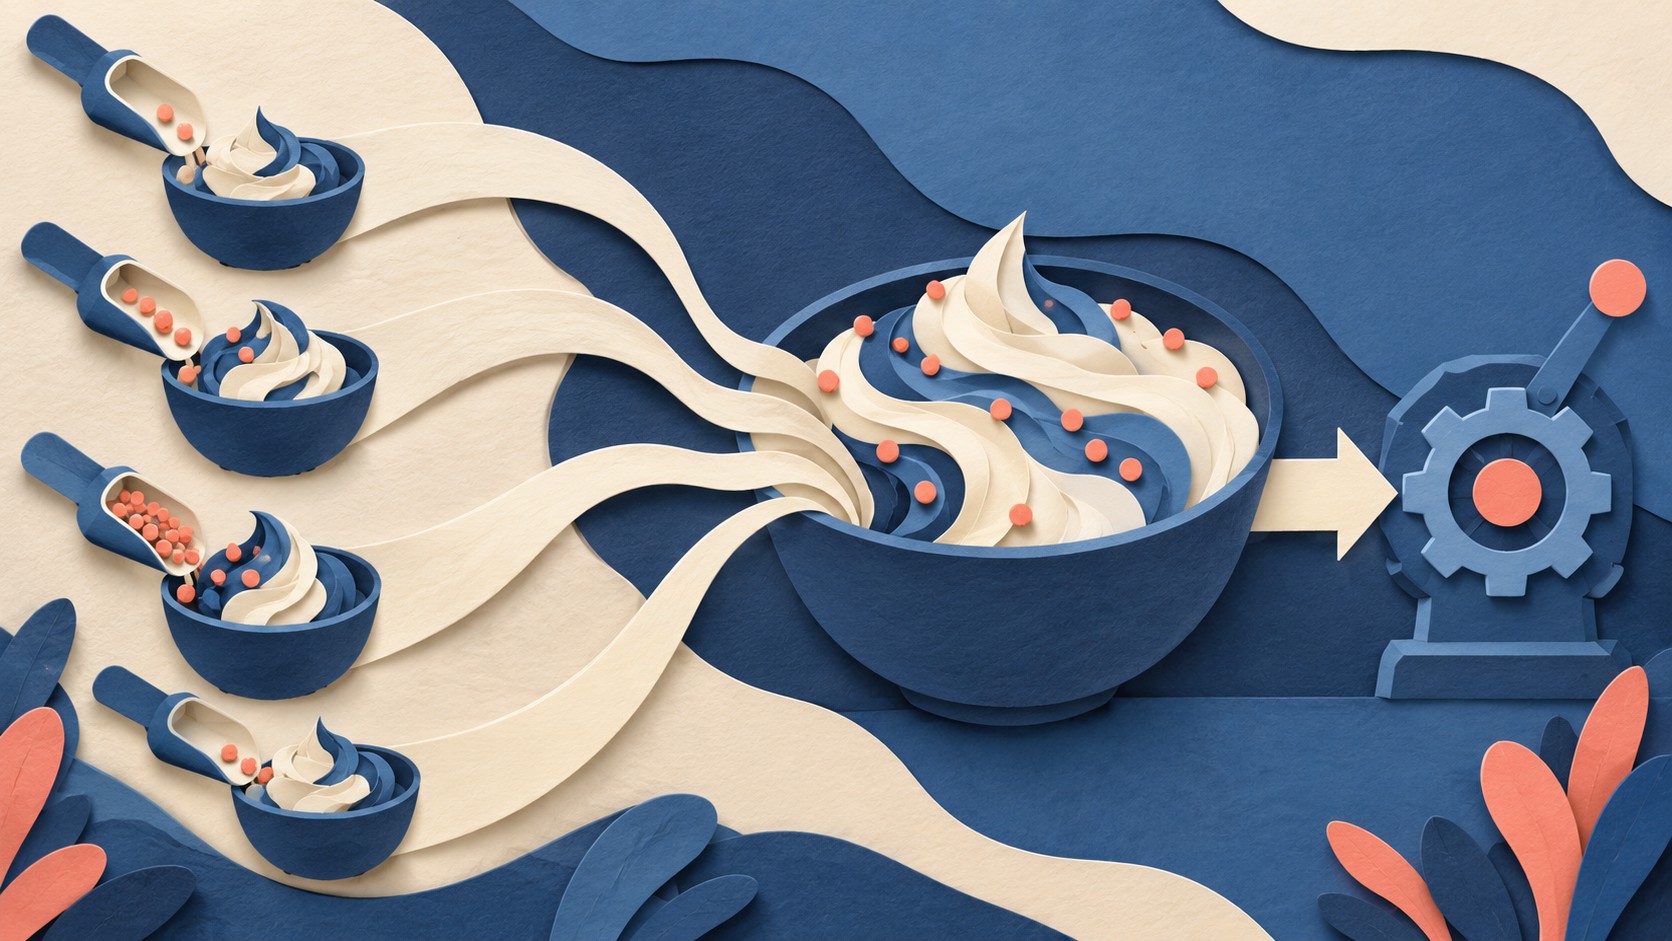
A training batch may be too large to fit in memory. Gradient accumulation lets the model process smaller batches in sequence and use their gradients for one optimizer update. Each small batch gets a forward pass and a backward pass. The optimizer updates the model after the chosen number of batches. This gives an update the contributions of a larger batch without loading all its samples at once. Hugging Face’s Accelerate guide describes this pattern.
Several batches contribute to one update
A backward pass calculates gradients for the model’s parameters. In PyTorch, another backward pass adds to the gradients already stored for those parameters. That behavior makes accumulation possible. Clear the gradients after the optimizer update so the next group of batches starts fresh. PyTorch’s gradient recipe explains why clearing them matters.
The group of small batches is often called an accumulation window. Hugging Face’s toy example processes four batches of two samples, then compares the result with an update on one batch of eight. The example reports the same final model weight. It shows the intended calculation in a simple case. When adapting the pattern, the loss calculation still needs to match the samples or tokens that contribute to each update. The Accelerate guide shows both the comparison and the loss details.
The optimizer’s schedule follows updates, rather than individual backward passes. If several batches now share an update, the run has fewer optimizer updates for the same number of batches. Hugging Face notes that accumulation changes the step count used for training and that Accelerate adjusts this count by default. A hand-written loop needs its own update and scheduler timing. Accelerate’s guide places the scheduler step with the optimizer step.
A mean loss needs the right weight
In a basic loop with equally sized batches and a mean loss, each small batch’s loss is divided by the accumulation count before its backward pass. The gradients then add to the average contribution for the whole window. The manual example in Accelerate’s guide makes that division explicit.
Accelerate offers a shorter route. Set gradient_accumulation_steps when creating the accelerator, then put each batch’s training work inside accelerator.accumulate(model). Its prepared optimizer waits for the appropriate update, and accelerator.backward(loss) handles the usual loss adjustment. The guide says to perform one forward and backward pass inside each accumulation context. Keep the optimizer step, scheduler step, and gradient clearing inside that context as shown in its finished example.
This convenient division assumes that each batch mean deserves the same weight. That assumption can fail when batches contain different numbers of items that contribute to the loss. An average of batch averages gives a short batch the same weight as a long one. The denominator must represent the contributing items across the entire update window. Hugging Face’s explanation of the token-level loss issue sets out that distinction.
Variable-length text needs a shared token count
Causal language model training makes the weighting problem concrete. Sequences can contain different numbers of tokens, and padding tokens do not contribute to the loss. For an accumulation window, sum the loss over its contributing tokens and divide by the total number of non-padding tokens in that window. Averaging a separate token mean from each small batch produces a different result when those token counts differ. Hugging Face’s loss analysis identifies this error, and the Accelerate guide provides an example that counts tokens across the window.
That example gathers the token counts across devices before calculating the denominator. It also accounts for how distributed training and Accelerate average gradients. Those details matter when writing a custom distributed loop. Copying only the token-count division from the example would omit part of its calculation. Follow the complete distributed loss example for that setup.
Distributed training has a communication cost
In distributed data parallel training, devices synchronize gradients. Synchronizing after every small batch can add communication that the update does not yet need. Accelerate’s accumulation context handles synchronization around the update window. Its gradient synchronization guide explains why this matters.
There is a memory tradeoff for Fully Sharded Data Parallel training. The same guide warns that delaying synchronization with no_sync can require more memory. It describes a plugin setting, sync_each_batch=True, for memory-constrained runs that need to synchronize each batch. That choice adds communication, so the appropriate setting depends on the training setup. Accelerate documents both effects.
What to do
- Choose a small batch that fits in memory. Decide how many of those batches should contribute to each optimizer update. Use Accelerate’s accumulation context when training with Accelerate.
- Check what the loss averages. For variable-length token tasks, count contributing tokens across the update window and use that total as the denominator. Follow the full loss example when training across devices.
- Check that optimizer updates, scheduler steps, and gradient clearing occur at the intended boundary. PyTorch accumulates gradients between backward passes.
- If distributed training becomes slow or a sharded run exceeds memory, inspect synchronization. Accelerate’s synchronization guide covers the communication and memory tradeoff.
The Campfire
No commentsNobody has pulled up a log by this one yet. Be the first to say what you make of it.
Held for the desk. It appears after a look.