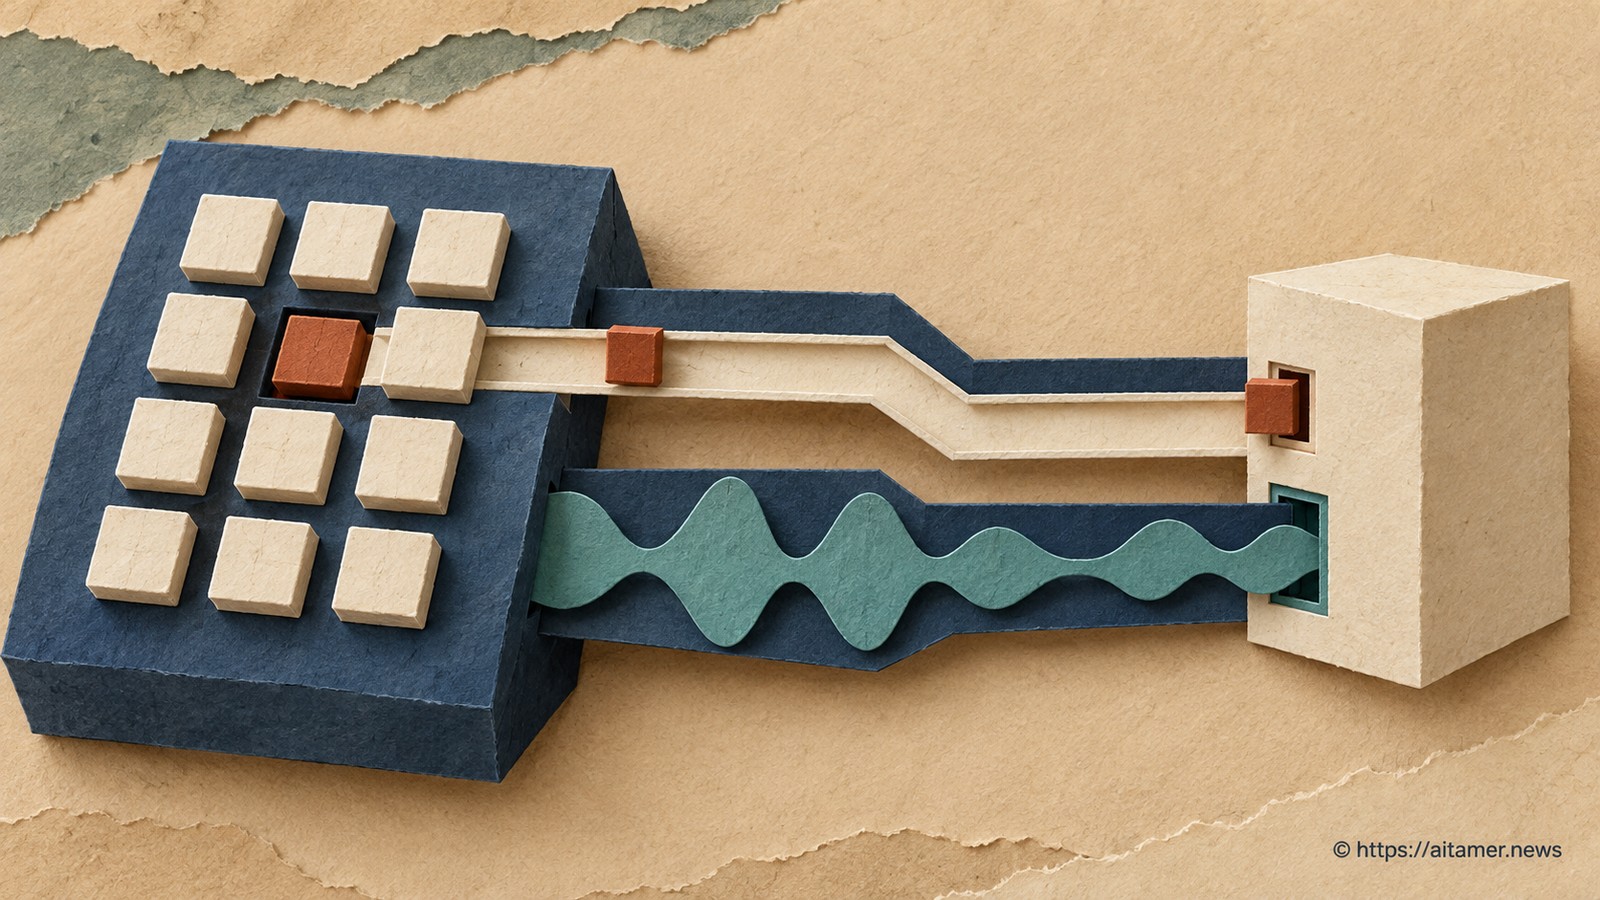
A caller hears “Press 1 for billing, or tell me what you need.” In a voice assistant, those are two input paths. The caller may press a key, speak the word “one,” or do both. Treating every input as a transcript obscures which action the caller actually took.
Twilio’s Media Streams message reference gives keypad input its own WebSocket event. In a bidirectional stream, an inbound touch-tone key press produces a message with event: "dtmf", a streamSid, a sequenceNumber, and a dtmf object. That object contains digit and a track whose documented value is inbound_track. Audio arrives in separate media messages whose payload is base64-encoded audio. The keypad digit is already a detected symbol; it does not need speech recognition to become one.
A useful application boundary is a dispatcher on event. Send inbound media payloads toward the audio and speech pipeline. Send dtmf.digit toward a keypad handler. Both handlers can eventually propose the same domain action, such as selectDepartment("billing"), while retaining the source of the proposal. A spoken “one” may be part of “one more question,” so the speech path still needs context and intent interpretation. A dtmf digit can be mapped according to the prompt that was active for that call.
For example, after the billing prompt, digit: "1" can select billing immediately. If speech recognition subsequently yields “billing,” the application should define whether that is a second request, a confirmation, or stale input from the same interaction. An action identifier or short-lived prompt state can prevent duplicate transfers. This deduplication policy is application logic; the dtmf event alone does not establish the caller’s broader intent.
There is an important coverage limit: Twilio documents dtmf messages here for bidirectional Media Streams. Do not design a unidirectional stream consumer around receiving this event. Also, use sequenceNumber to reason about message order, rather than inventing a timestamp for the key press from an audio chunk. If a digit is sensitive, avoid putting its value in ordinary transcript logs.
The implementation decision is simple: keep transport events typed until the application has enough context to turn them into actions. That lets an AI voice agent honor keypad shortcuts without asking a language model to infer a button press from sound.
The Campfire
No commentsNobody has pulled up a log by this one yet. Be the first to say what you make of it.
Held for the desk. It appears after a look.