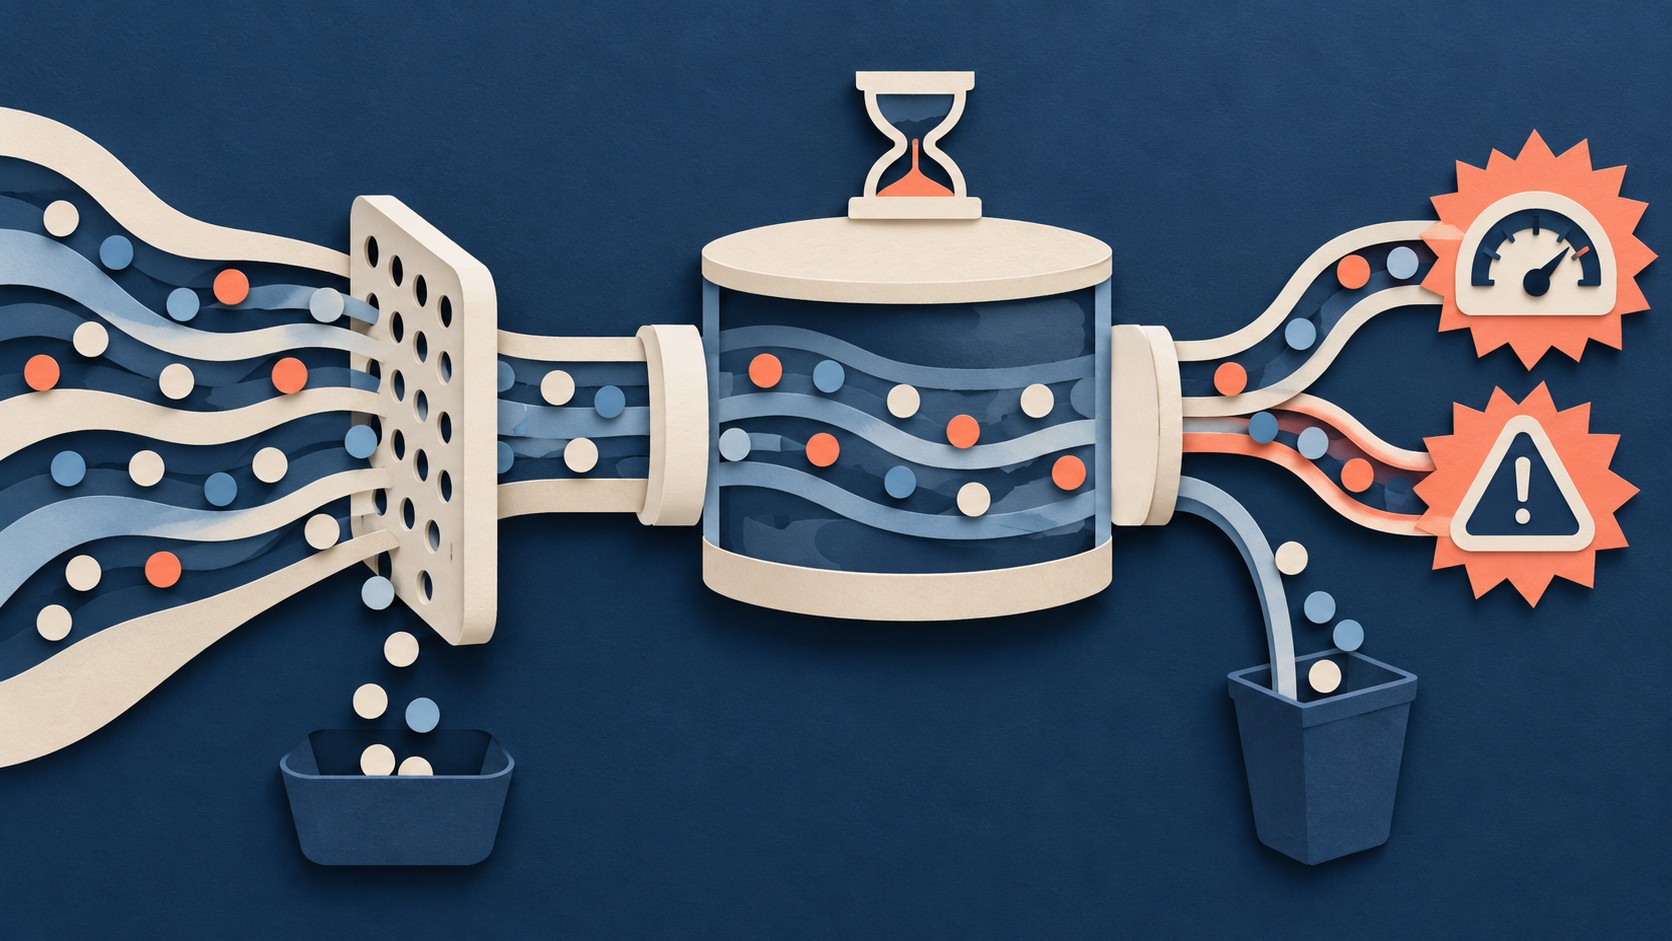
An agent run may look routine when it starts. A tool can fail near the end, or the run can take much longer than its peers. If the sampling decision happens at the start, those later facts cannot guide it. OpenTelemetry describes agent invocation and tool execution spans, so a trace can carry the steps that led to the final outcome. Its sampling guide defines a sampled trace as one selected for processing and export. Agent span conventions and the sampling guide provide the starting point.
Head sampling decides before the outcome
Head sampling makes the keep or drop decision early. A common method uses the trace ID and a chosen probability. The guide calls this approach efficient and easy to configure. It can keep complete traces at a consistent rate when the decision applies throughout the trace. It is a reasonable way to retain a view of ordinary traffic while controlling volume. OpenTelemetry explains the method and its limits.
That early choice has a direct cost for agent runs. A trace dropped at the start cannot be selected later because the final tool call failed. A trace that grows slow after repeated work faces the same problem. Head sampling alone cannot guarantee that every trace containing an error survives. Raising the probability improves the odds, but still does not select runs by their eventual outcome. The useful question is whether the team needs a representative slice of all runs or a record of particular outcomes. OpenTelemetry draws this boundary explicitly.
Tail sampling uses the finished work
Tail sampling considers all or most spans before deciding. OpenTelemetry gives error presence, overall latency, and span attributes as examples of selection rules. For agent work, this allows a policy to retain runs with failed operations or long duration while keeping a smaller sample of routine runs. The rule can consider a tool span that appears well after the agent invocation began. The sampling guide lists these criteria.
A collector policy needs a precise meaning for “failed.” The Collector’s tail sampling processor supports a span status policy for ERROR, a latency policy, and attribute policies. Its latency policy measures from the earliest span start to the latest span end. That span range may differ from the time a user waited for a final answer if the instrumentation covers a different boundary. Define the boundary first, then choose a slow-run threshold from the service’s own expectations. The processor documents these policies.
An error on one tool call does not always mean the agent run failed. A retry may succeed, or the application may handle the error. OpenTelemetry’s error guidance says handled or retried errors should not be reported as failures of the completed operation. Decide whether the retention rule means any failed step, a failed final run, or both. Mark the invocation outcome accordingly, and use a separate attribute if the product has an outcome that span status does not express. That distinction makes a retained trace easier to interpret. OpenTelemetry’s error guidance supports it.
Waiting has an operating cost
Tail sampling needs to hold spans while it waits to decide. The Collector processor groups spans by trace ID and keeps them in memory during that wait. Its decision timer is a configured wait; it does not prove that every span has arrived. A long-running agent or a delayed exporter can send a span after a decision. The processor documentation describes late spans that inherit an existing decision and cases where a new decision may be made after the old one is forgotten. Set the wait using actual run and delivery patterns. Then inspect late-span behavior. The processor describes the timer, memory, and late spans.
All spans for a trace must reach the same Collector instance for effective tail sampling. When the service grows beyond one instance, traffic spreading can split the trace. OpenTelemetry’s gateway guidance shows a first Collector tier routing by trace ID to a second tier that makes the decision. The processor also exposes signals for traces removed before sampling and spans arriving late. These help explain why important runs disappear despite a suitable policy. Gateway guidance and processor monitoring notes cover those risks.
If an earlier head sampler discards a run, a later tail sampler cannot inspect its missing spans. OpenTelemetry describes combining the methods to protect a busy pipeline. Accept that trade when lower intake volume matters more than retaining every eventual failure. If every failed run must remain eligible, preserve its spans until the tail decision. Keep a probability sample of the remaining runs as well, so the retained set includes routine behavior. The sampling guide discusses both the combination and representative samples.
What to do
- Trace an agent invocation and its tool calls under the same trace. Check that the recorded end of the invocation matches the outcome users see. Agent span conventions describe these operations.
- Write down which failures matter: a failed final run, any failed tool, or a product-specific outcome. Add a slow-run rule based on the trace duration you actually record. Use status and attribute policies that match those definitions. Error guidance and processor policies show the available signals.
- Route each trace to one tail-sampling Collector. Preserve eligible spans upstream. Add a probability policy for ordinary runs, then watch early drops and late spans while testing failed, recovered, and slow runs. Gateway guidance and processor monitoring notes explain the checks.
- Review what retained spans contain. The agent conventions warn that input and output messages, tool arguments, and tool results may contain sensitive data. Filter or truncate those fields before broader retention. Agent span conventions describe the exposure.
The Campfire
No commentsNobody has pulled up a log by this one yet. Be the first to say what you make of it.
Held for the desk. It appears after a look.