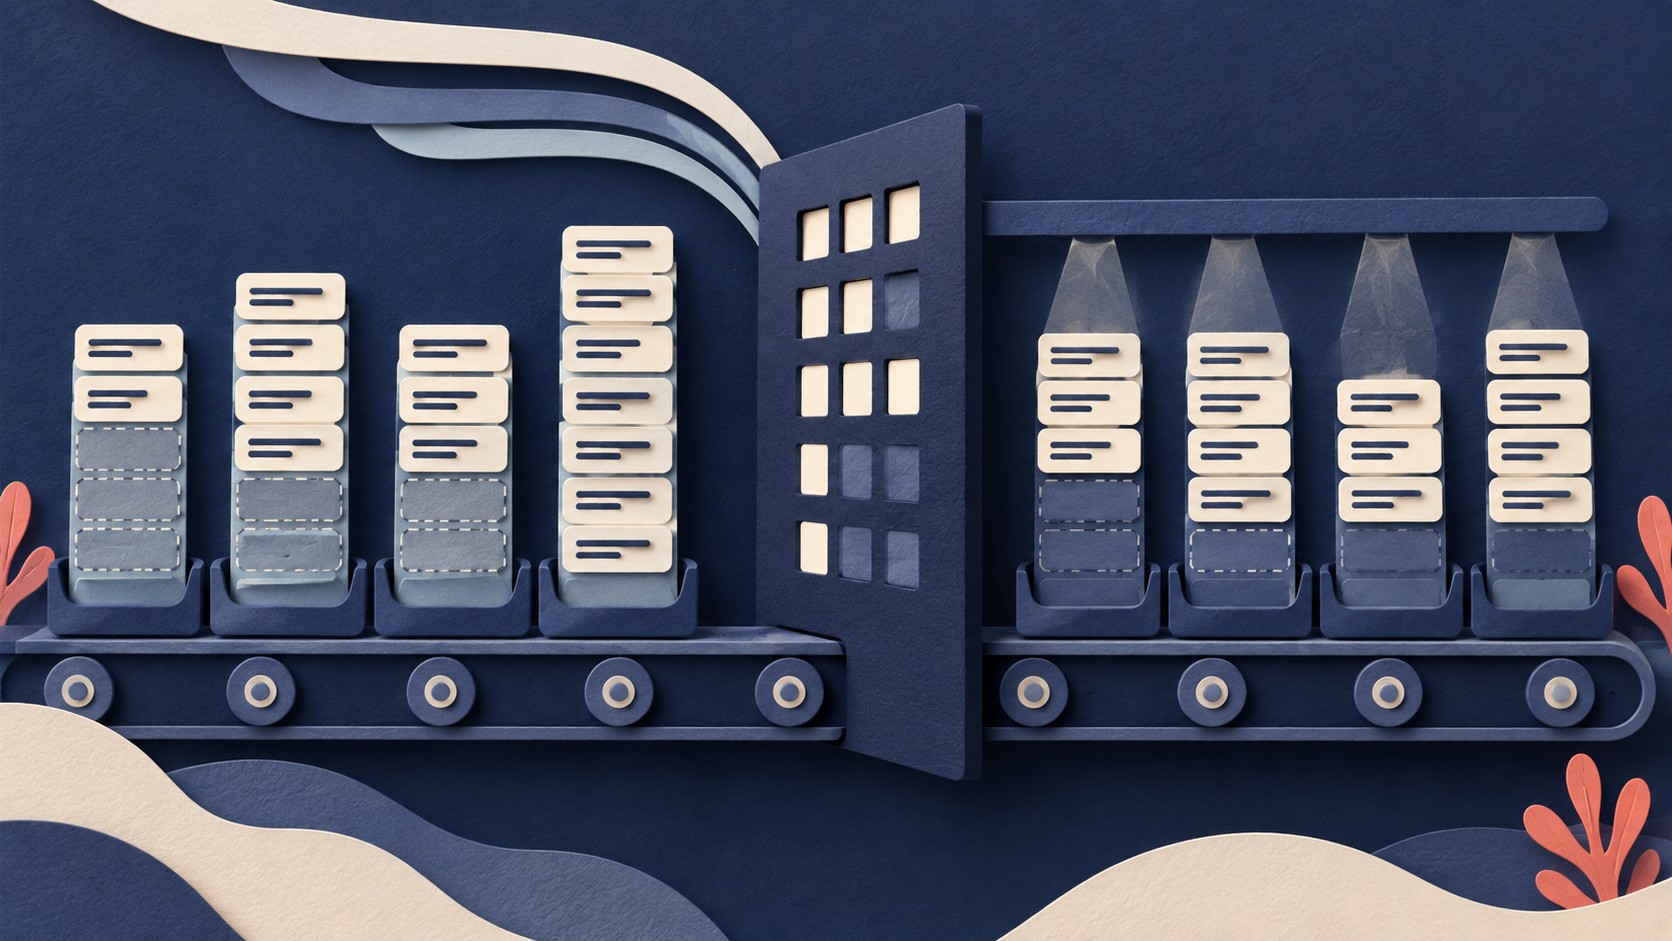
Why a batch needs padding
A tokenizer turns each prompt into token IDs. Prompts can produce sequences of different lengths. A model batch needs a rectangular input tensor, so shorter sequences receive special padding tokens until they match the chosen length. Hugging Face’s padding guide shows how padding=True extends shorter inputs to the longest sequence in a batch.
Those added positions make the batch fit together. They contain no words from the shorter prompt. An attention mask tells the model which positions to attend to and which to ignore. The Transformers glossary describes this mask as an optional input when batching sequences.
How the mask marks padding
In the glossary’s BERT example, the tokenizer returns both input_ids and attention_mask. The shorter sequence gains padding IDs on its right. Its mask has 1 at positions to attend to and 0 at padded positions. The longer sequence has 1 across its positions because it needs no padding. The padded IDs remain in the batch, while the mask tells the model to leave them out of attention.
The mask gives an instruction for each position in each sequence. Prompts can therefore share the same tensor shape while keeping their own boundaries between tokens and padding. Hugging Face’s preprocessing guide shows returned masks alongside padded token IDs for a batch of sentences.
Padding and truncation address different length problems. Padding extends short inputs to a chosen length. Truncation shortens inputs that exceed a chosen limit. A padding mask cannot recover text removed by truncation. The padding guide lists separate controls for these operations.
What to do
Use the tokenizer paired with the model. Tokenize prompts as a batch with padding enabled. Inspect input_ids and attention_mask together: padded positions should line up with mask values of 0. Pass the returned mask with the token IDs when calling the model. If you also enable truncation, choose its limit deliberately because truncation removes tokens from long inputs.
The Campfire
No commentsNobody has pulled up a log by this one yet. Be the first to say what you make of it.
Held for the desk. It appears after a look.